 NexAIX-官方博客
When evaluating AI models, focus on three conditions: controllable samples, fixed variables, and reproducible results. Instead of relying on scores from public benchmarks, build your own business evaluation set: use the same data, the same code, and only change the model, drawing conclusions on your own call chain. In August 2026, OpenRouter launched real-time retrieval benchmarks for agents and a granular Analytics API, shifting evaluation focus from static leaderboards to real call chains—this validates the necessity of self-built comparisons.
What Public Benchmarks Can and Cannot Answer
Public benchmarks can answer approximate capability tiers: which models are stronger on general tasks and worth including in your candidate pool. But they cannot answer your specific questions: whether a model passes under your prompt style, your data distribution, and your output constraints. High benchmark scores but poor real-world performance often occur because the evaluation samples do not match your business distribution. Therefore, the correct approach to AI model evaluation is: first use benchmarks to select 3-5 candidates, then build a comparison set with your own business samples for final decisions.
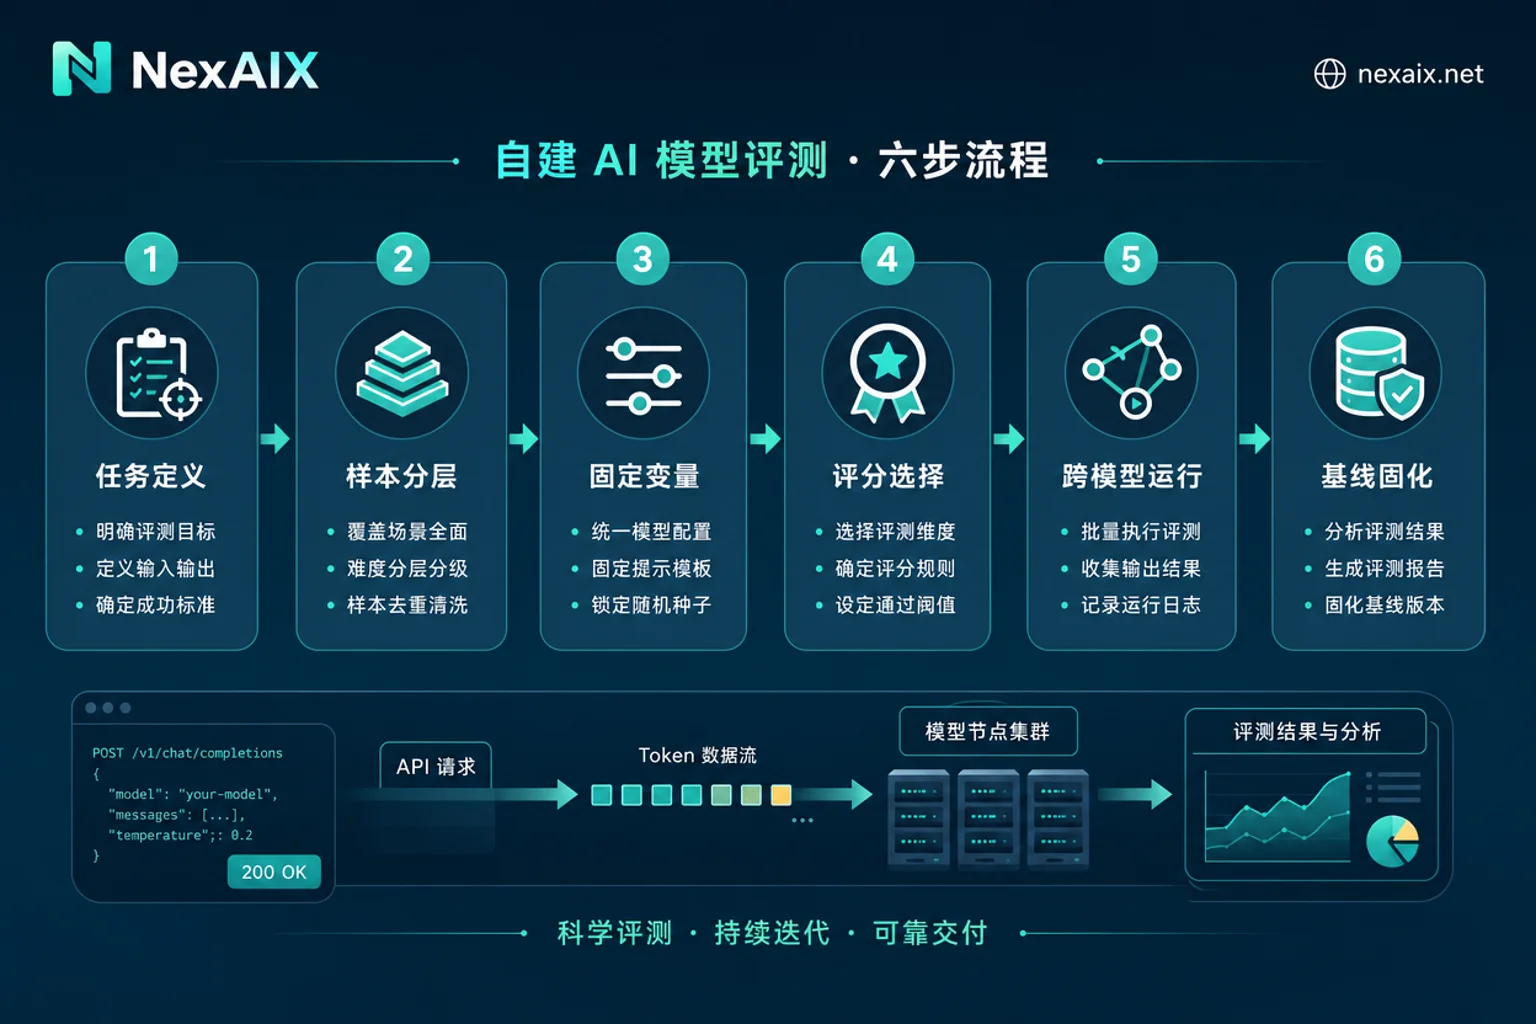
Step 1: Write the Evaluation Goal as a Testable Task Definition
Before collecting samples, write a clear task definition. A testable task definition includes three parts:
- Input format: field types, length ranges, language, context source.
- Output constraints: JSON Schema, required fields, length limits, format requirements.
- Pass criteria: separate hard failure items (e.g., missing required fields, JSON parsing failures) from scoring items (e.g., relevance, completeness).
"Testable" means two people can independently evaluate the same sample and reach the same conclusion. If not, revise the definition before collecting samples.
For example, for RAG Q&A, the definition could be: input is a question and retrieved documents, output must include citations, and the answer must be supported by the document content; hard failures are no citations or nonexistent citations. Structured extraction requires output conforming to a specified schema, with missing fields or type errors causing failure.
Step 2: How to Stratify the AI Model Evaluation Set and How Many Samples Are Enough
Before answering "how many samples are enough for an evaluation set," stratify first: bucket by task type, difficulty, and edge cases, ensuring each bucket has coverage before considering total quantity. Edge cases include empty values, long context, adversarial inputs, multilingual, etc.
Sample size depends on two factors: the minimum difference you want to detect and the variance of the task. OpenAI's evaluation engineering guide explicitly states that confidence intervals and statistical power depend on sample size and task variance—small samples cannot detect small true performance drops, and high-variance tasks require more samples and multiple resampling. So "a dozen or so samples for model selection" can only exclude obviously unusable candidates, not serve as a basis for production release. Practically, start with a 30-sample smoke test, observe pass rates and variance across buckets, then progressively expand samples based on the target minimum detectable difference.
Step 3: Fix Variables—Record Model ID, Sampling Parameters, and Prompt Version
When AI model evaluation results are inconsistent, don't suspect the model first; check if variables are locked. Every result must include the following fields:
| Field | Description |
|---|---|
| Request model | The model name you requested |
| Response model | The actual model executed (must be checked for consistency) |
| temperature / top_p / seed | Sampling parameters |
| Prompt version or hash | Lock prompt changes |
| Context length | Input token count |
| Timestamp / request ID / status code | Traceability |
Fixing seed and temperature only reduces non-determinism; it doesn't eliminate it. Therefore, resample the same sample multiple times (e.g., 3-5 times) and evaluate stability using the variance of pass rates. If results drift, first compare the response model field with the request—this takes priority over suspecting the model itself.
Step 4: Choosing Scoring Methods—Exact Match, Schema Validation, Model Review, and Human Spot Checks
Different tasks require different scoring methods; using the wrong one can mask or amplify differences:
| Task Type | Scoring Method | Key Points |
|---|---|---|
| Deterministic answers (e.g., classification, extraction) | Exact match or rules | Define equivalence rules, e.g., synonyms, format normalization |
| Structured output | JSON Schema validation + field-level comparison | Validate required, type, value range, then compare field values |
| Open-ended generation (e.g., summarization, creative writing) | Model review + human spot checks | Fix the review model and scoring rubric, calibrate consistency with human judgment |
Model review itself is a variable that can drift; record its version and parameters just like the model under test. For human spot checks, randomly sample a fixed number of cases per bucket, at least a few per bucket, until the agreement rate between human and review model stabilizes; if unstable, adjust the rubric first and then expand the spot check sample.
Step 5: Run the Same Set Across Models, Only Changing the Model Parameter
Engineering-wise, using an OpenAI-compatible API for multi-model comparison is simplest: same data loading, same prompt rendering, same scorer, with the model as the only variable in a loop. Here you can leverage NexAIX: it provides an OpenAI Chat Completions compatible endpoint https://api.nexaix.net/v1,同一套评测脚本只换 model parameter to complete cross-model comparison. The response body's model field corresponds to the actual executing model, and when overloaded, it returns a standard 429 error rather than silently switching to a cheaper model—these two points are prerequisites for attributable and reproducible evaluation results.
It's recommended to first run a small-scale smoke set with test credits to validate scripts and scorers, then expand to the full evaluation set. Handle concurrency with backoff to avoid missing samples due to rate limits being misread as capability differences. For specific available models and specifications, refer to NexAIX's current model page.
Step 6: Solidify Results as a Regression Baseline, When to Rerun
A baseline snapshot should include: dataset version, prompt version, model ID, sampling parameters, pass rates and variance per bucket, and pass thresholds. Thresholds should be set based on baseline variance, not an arbitrary absolute score—if variance is high, loosen the threshold to avoid misjudging degradation due to random fluctuation.
Events that trigger a rerun include: model changes, model version or alias changes, prompt modifications, context strategy adjustments, and provider switches. Write rerun conditions into CI so that every change automatically runs evaluation, ensuring continuous quality protection.
Why Black-Box Auto-Routing Breaks the Comparison Premise of AI Model Evaluation
Adaptive routing lowers exploration barriers and dynamically optimizes cost, but in evaluation and regression testing, it makes the actual executing model inconsistent with the requested model, violating the single-variable assumption. How to identify: check the returned model ID, observe whether it degrades or returns 429 when overloaded, and send the same sample repeatedly to see if the model field changes. You can use routing during exploration, but during evaluation and baseline phases, you must explicitly lock the model. For more details, see: AI API Selection: Auto-Routing or Locking Models and Detecting Silent Degradation in Multi-Model API Gateways.
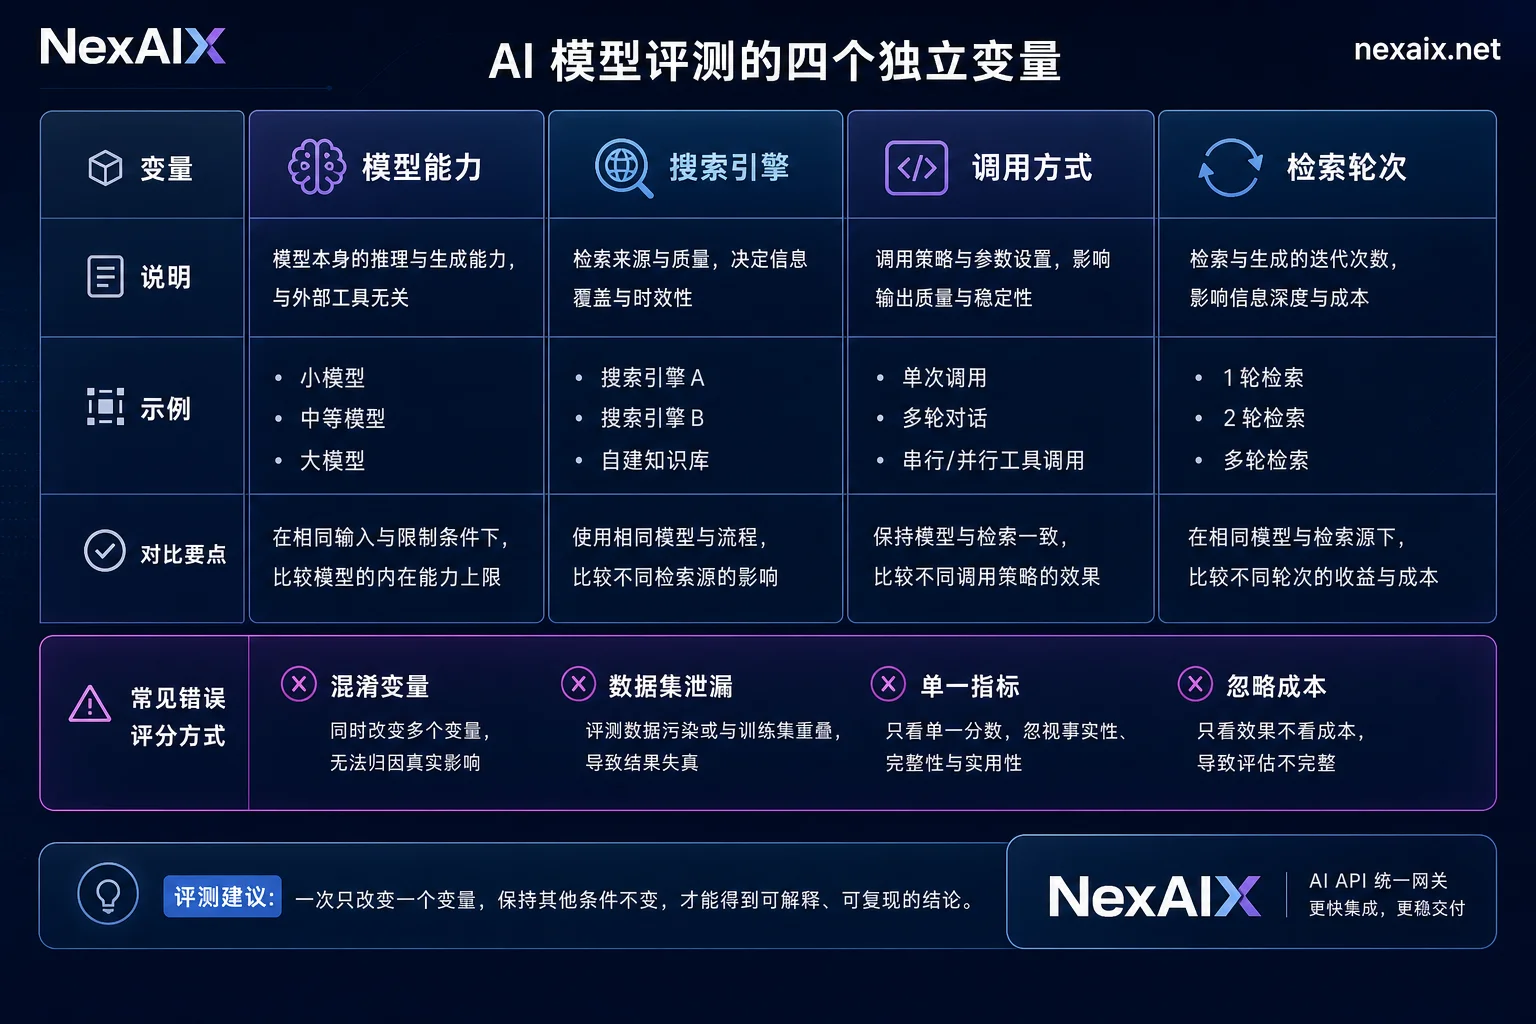
Retrieval Chains Need Separate Evaluation: Engine, Depth, and Model Are Three Variables
To evaluate agent web search effects, don't mix model and retrieval together. OpenRouter's August 2026 approach separates model capability, search engine, invocation method, and retrieval round budget (1/5/25 rounds) as independent variables for comparison—mixing them makes retrieval quality issues be misjudged as model capability issues. When designing comparisons, fix the model and vary only the search engine, or fix the engine and vary retrieval rounds. Record additional fields: retrieval rounds, number of hit sources, whether tool calls were triggered.
This Week's Actionable Evaluation Checklist
Check against this list to ensure every variable in AI model evaluation is recorded and auditable.
| Check Item | Pass Criteria |
|---|---|
| Task definition is testable | Two people independently evaluate the same sample and reach the same conclusion |
| Buckets cover edge cases | At least 1 case each for empty values, long context, adversarial, multilingual |
| Sample size matches variance | High-variance tasks have been resampled multiple times |
| Parameters and model ID recorded | Each result includes model, temperature, seed, prompt version |
| Scorer version fixed | Review model and rubric have recorded versions |
| Concurrency and 429 handling | Backoff strategy in place, no missing samples |
| Baseline snapshot archived | Includes dataset, prompt, model, parameters, variance, thresholds |
| Rerun conditions in CI | Model change or prompt modification triggers evaluation automatically |
FAQ
How many samples are enough for an evaluation set?
There is no fixed number; it depends on variance and the minimum difference you want to detect. First bucket by task to ensure edge case coverage, then use a small batch of real samples (about 30 for a smoke set) to validate scripts and scorers, then progressively expand based on the target minimum difference and within-bucket variance—the larger the variance and the smaller the difference to detect, the more samples needed; small samples can only exclude obviously unusable candidates, not serve as a release basis.
Eval results inconsistent after changing models, what to do?
Check in order: first verify the response model matches the request, then check if temperature/seed are fixed, then confirm the prompt version hasn't changed, and finally consider sampling variance—resample multiple times to estimate fluctuation. If all these are normal, then suspect the model itself has changed.
Should I use a model as a judge?
Yes, but you must fix the review model and scoring rubric, and record versions. The review model itself can drift, so use human spot checks to calibrate consistency. Spot check a fixed number of cases per bucket (at least a few per bucket) randomly until the agreement rate between human and review model stabilizes. If agreement is poor, adjust the rubric first.
High benchmark scores but poor actual performance, why?
The benchmark samples don't match your business distribution, or your task constraints (e.g., output format) aren't reflected in the benchmark. Additionally, benchmarks may only test single turns, while your scenario is multi-turn. The solution is to build your own comparison set with real business samples.
After switching providers, which items to rerun?
At least rerun the full baseline: because providers may route differently, causing the actual executing model to differ. When rerunning, first check the response model field to confirm the executing model is the same. If the provider doesn't support explicit model locking, consider switching or adding validation.
For more engineering details on model locking and variable control, refer to OpenAI-compatible API model migration and regression validation and AI API 429 error troubleshooting and retry backoff.
Start with Step 1: write out the task definition, select 30 real business samples, and run a smoke set to confirm scripts and scorers work, then expand. When comparing across models, record the response model field to confirm the executing model matches the request.




Comments(0)