 NexAIX-官方博客
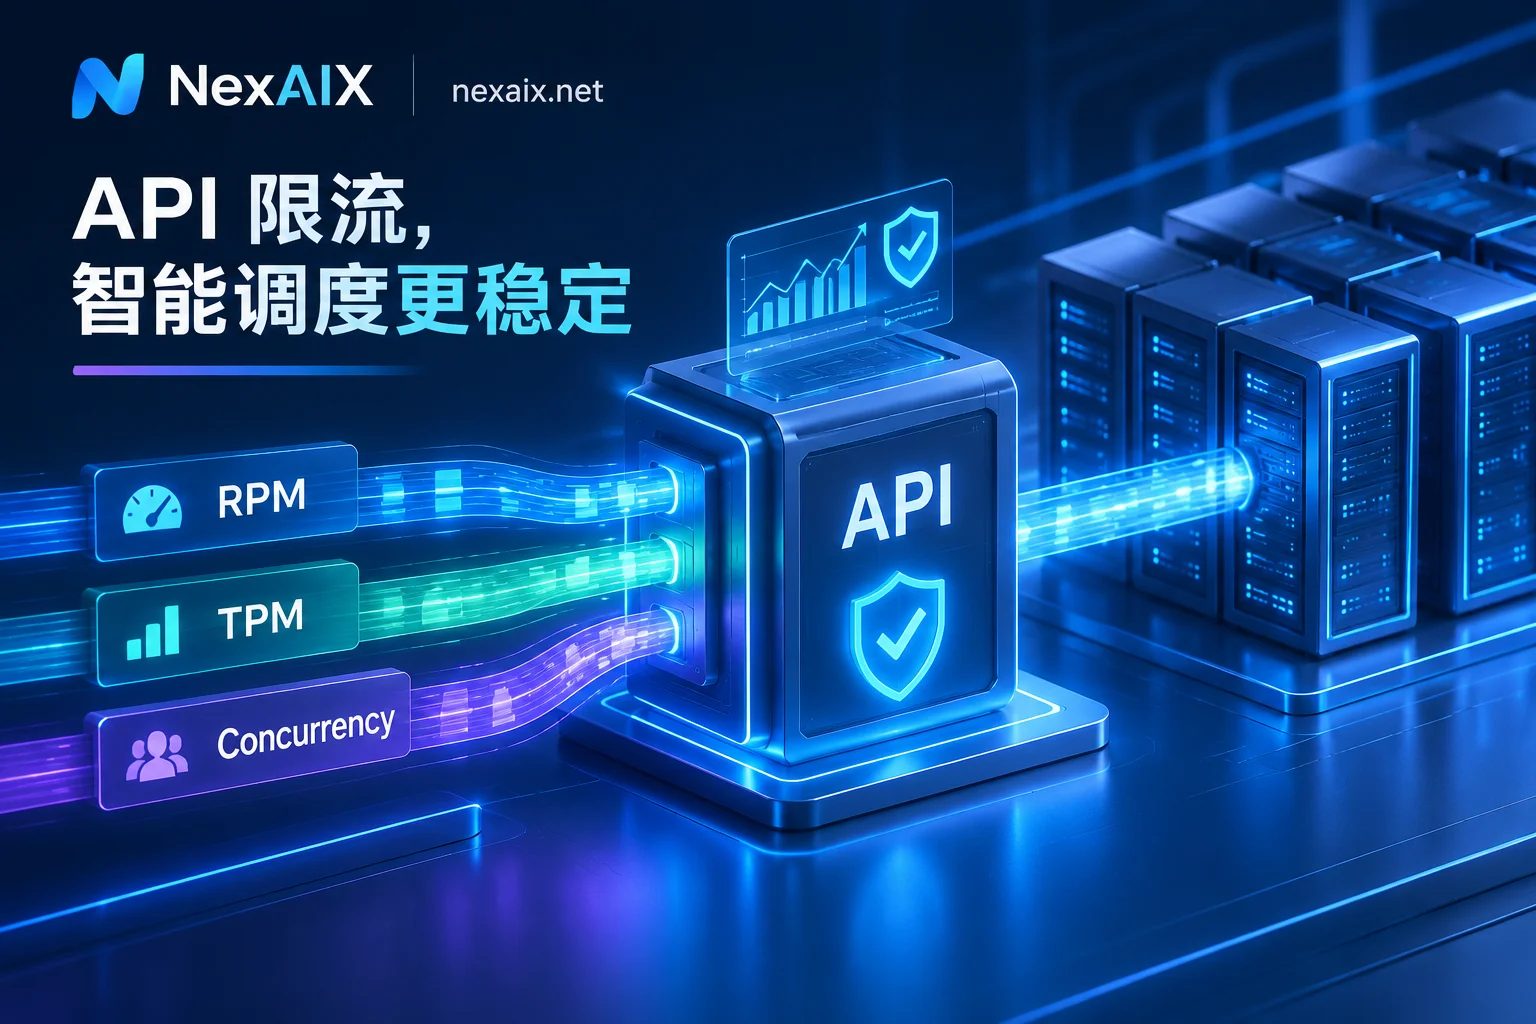
AI API Rate Limiting in Production: Diagnosing RPM, TPM, and Concurrent Request Bottlenecks
Production teams often see 429 errors even at low request rates—why? This article breaks down the three rate-limiting dimensions (RPM, TPM, and concurrency), exposes hidden incidents from shared quotas and non-standard gateway hangs, and provides a complete production solution from Retry-After backoff and per-key quota isolation to hybrid scheduling with dedicated compute and official channels.
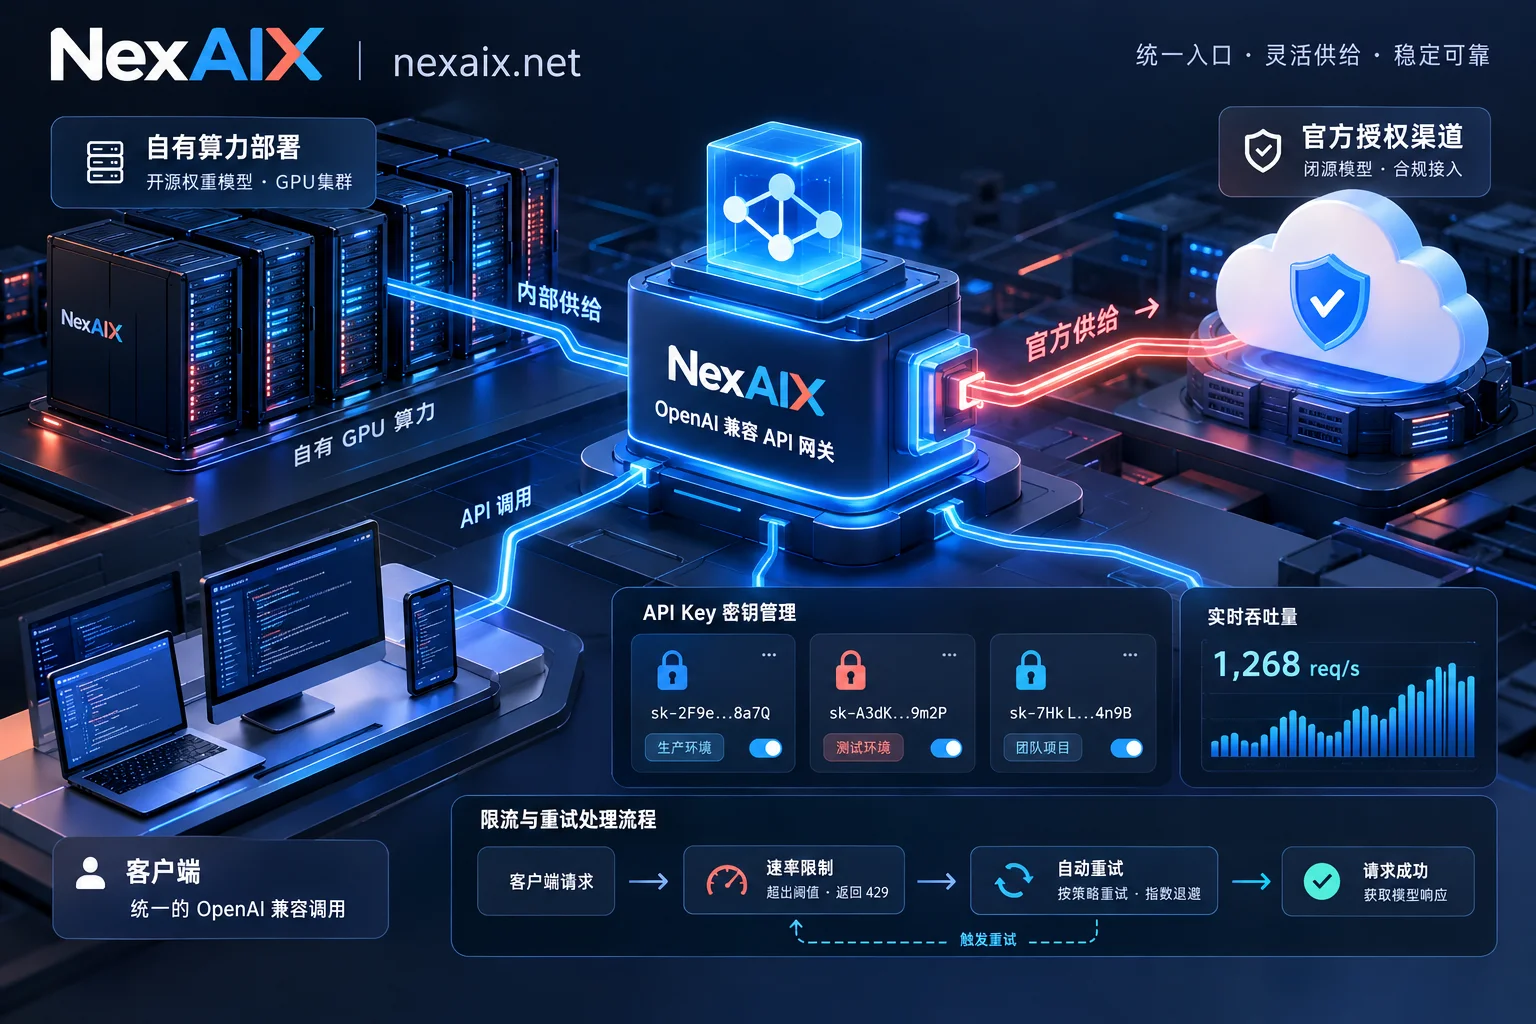
High Availability and Security Guide for LLM APIs in Production: Coping with Single Points of Failure, Key Leaks, and Compute Throttling
Combining recent industry hot topics such as LLM service outages, API key leaks from third-party tools, and tightening compute for leading models, this article provides an in-depth analysis of practical solutions for production-grade LLM API calls in disaster recovery architecture, per-key isolation, and selection of self-owned compute and officially authorized channels.