NexAIX-官方博客
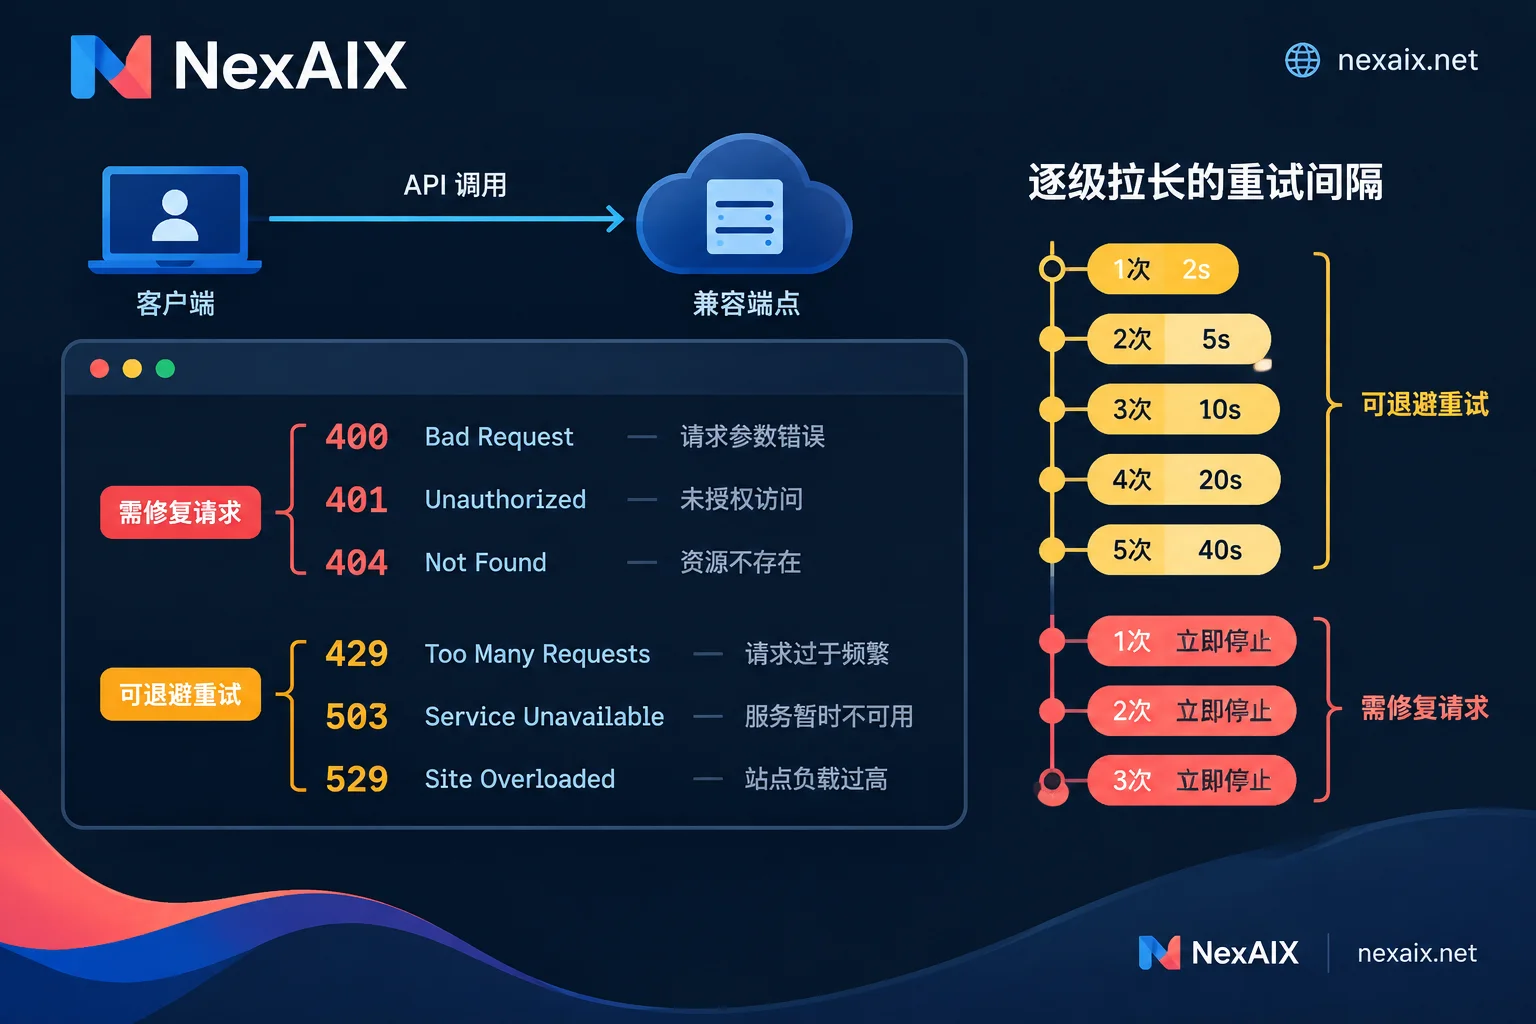
How to Read AI API Error Codes: Causes, Retries, and Fallbacks for 400, 401, 404, 429, 5xx, and 529
Explains common LLM API error codes by splitting them into "fix the request" and "wait and retry" categories, focusing on distinguishing 429 rate limits from quota exhaustion, and provides backoff retry, circuit breaker, and fallback patterns to avoid wasted retries and retry storms.
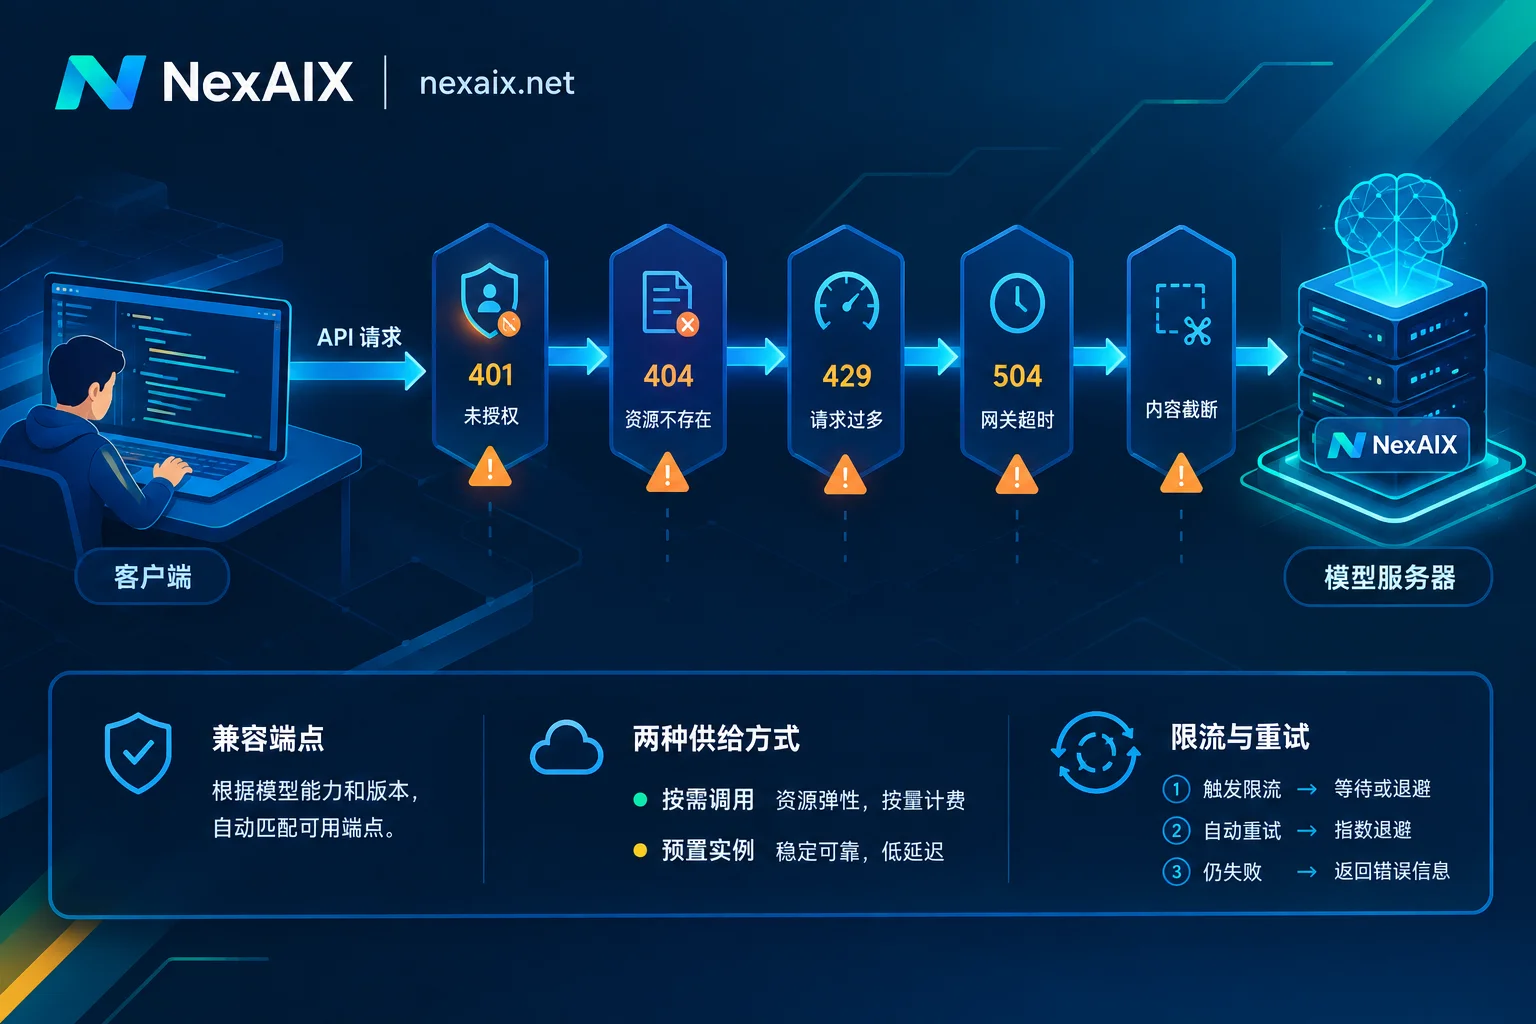
AI API Troubleshooting: From 401, 404, 429 to Timeouts, Truncation, and Suspected Model Downgrades, Locate in Order
When calling a large model API, first look at the status code and the error type in the response body, then use a minimal request to determine whether the problem is on the client or server side. This article explains how to diagnose and handle each type of issue in order: authentication, path and model ID, rate limiting and quotas, 5xx and timeouts, context truncation, and downgrade verification.
How to Measure and Improve AI API Throughput: Trade-offs Between Concurrency, RPM/TPM Rate Limits, and Latency
Learn how to measure AI API throughput using output tokens per second and completed requests per second, find the optimal concurrency via step-load testing, estimate capacity against RPM and TPM limits, and implement connection reuse, prompt caching, token usage control, and 429 retry with jitter to balance throughput and time-to-first-token.
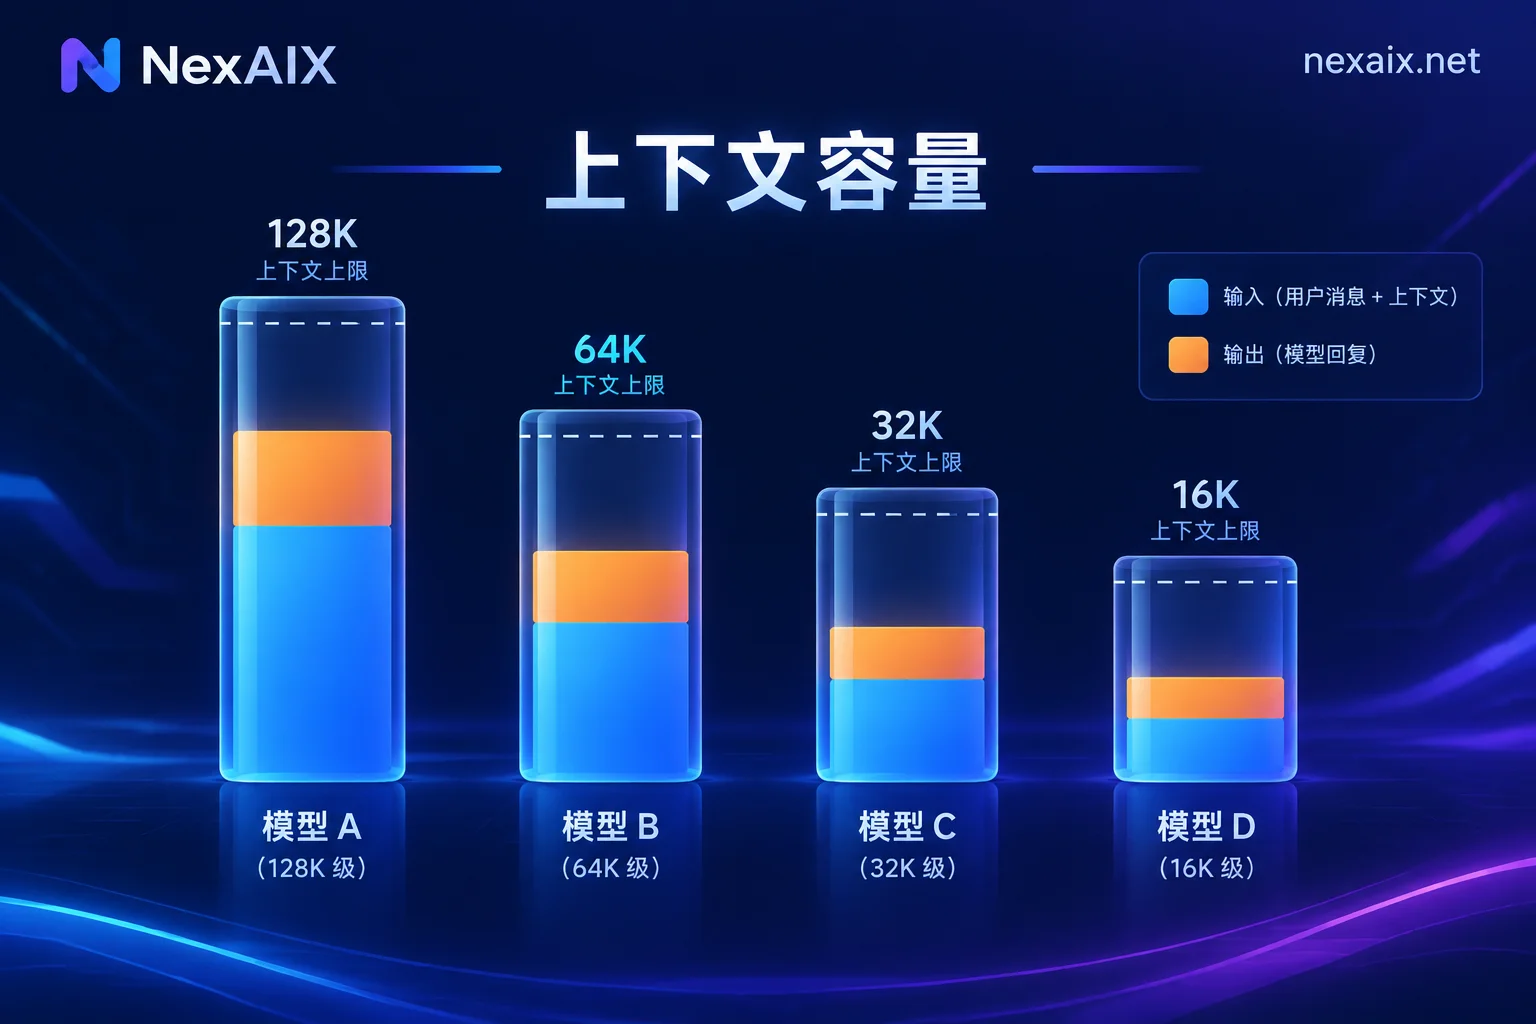
Model Context Window Comparison: How to Calculate Window and Output Limits, and Avoid Truncation, Latency, and Rate Limiting
Compare the context windows and single-output limits of representative versions like GPT-4o, Claude 3.5 Sonnet, DeepSeek-V3, and Gemini 1.5. This article explains how to calculate token budgets using "input + reserved output ≤ window" and choose the right window tier for your task. When output is truncated, use finish_reason and usage to pinpoint the cause. It also covers how to handle latency, attention decay, and TPM rate limiting caused by long contexts.
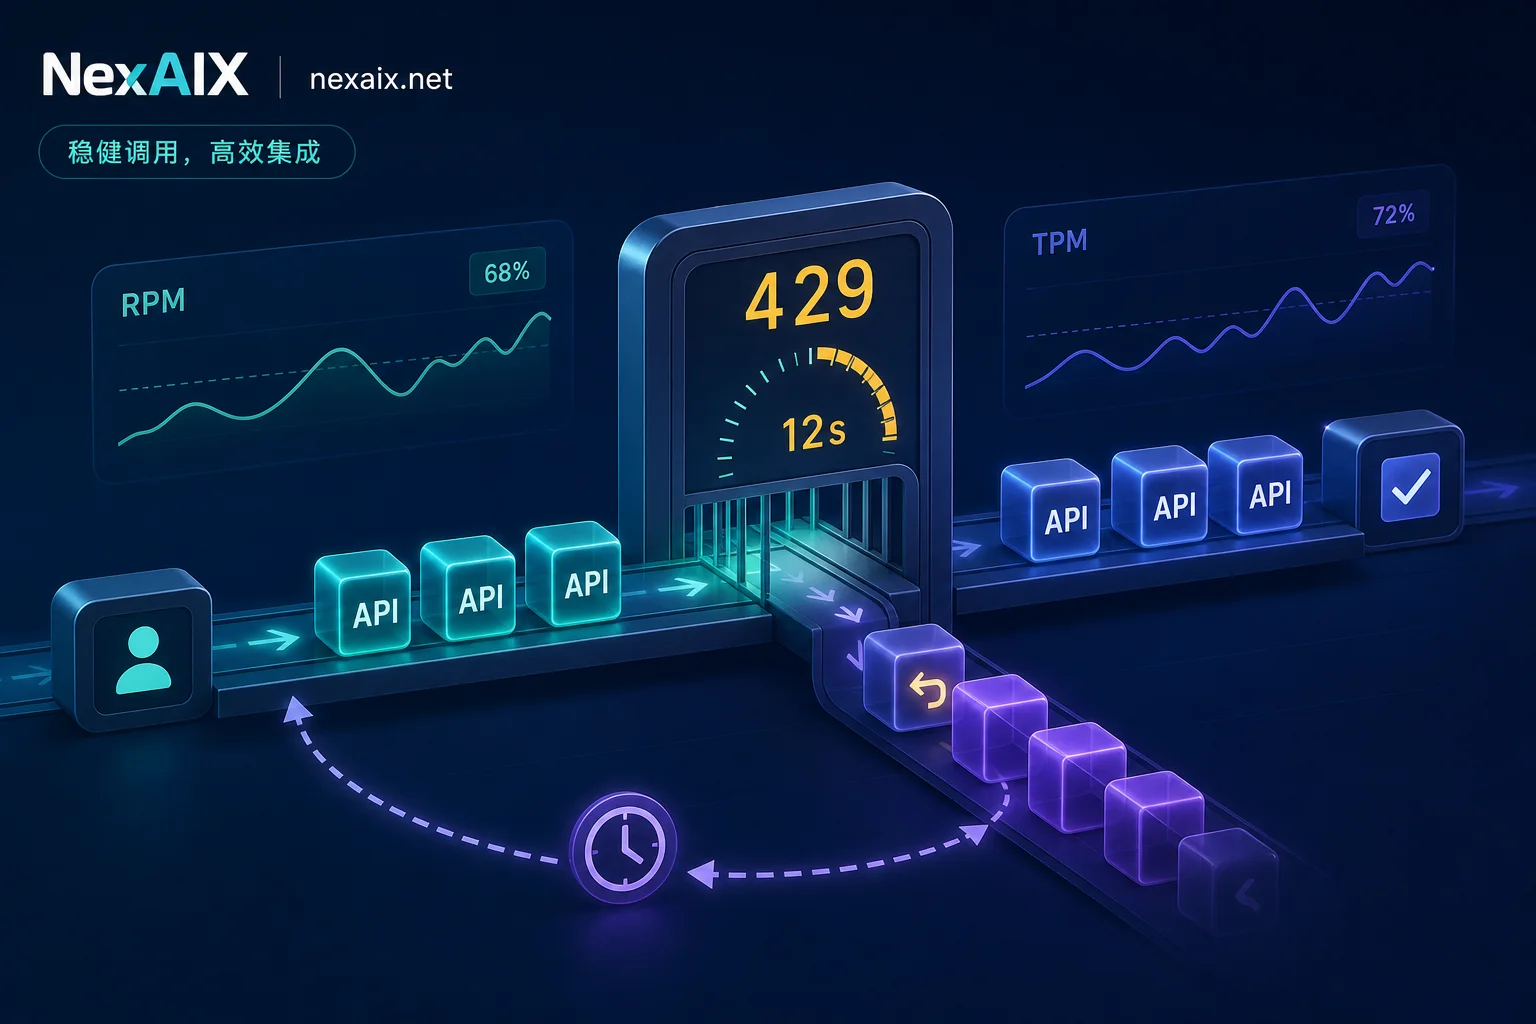
How to Handle AI API Rate Limiting: From 429 Headers to Backoff Retries and Traffic Isolation
When a large model API returns 429, check the response headers and error code before deciding on a retry strategy: honor Retry-After when present, and stop immediately if quota is exhausted. This article covers four dimensions of rate limiting, how to use six remaining-quota headers, an exponential backoff skeleton with jitter, and architectural mitigations like token buckets, tighter max_tokens, and per-key isolation.