NexAIX-官方博客
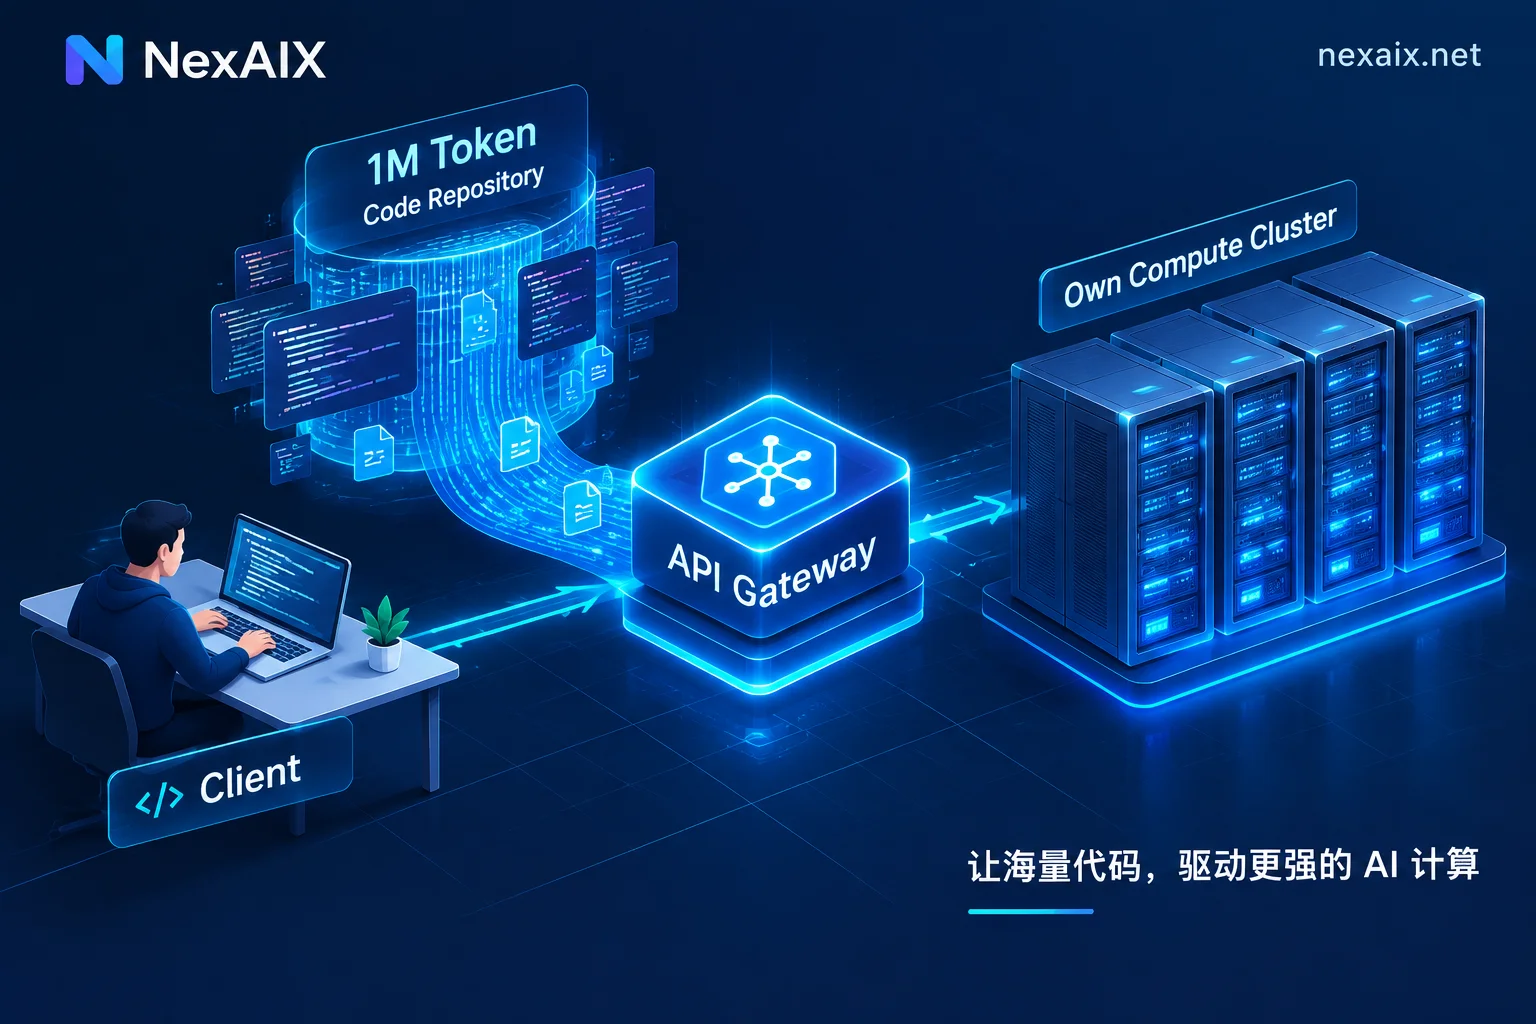
GLM API Integration and Selection Guide: From GLM-5.2/5.3 Million-Token Context to Coding Plan Rate Limits and Self-Owned Compute Calls
Explore the evolution of Zhipu's GLM-5.2 and GLM-5.3 open-source models, analyze the selection logic for GLM API in 1M ultra-long context and long-horizon agent scenarios. Compare subscription plan limitations with standard API differences, and provide an OpenAI-compatible integration solution based on NexAIX's self-owned compute cluster, including anti-silent replacement and zero-log verification.
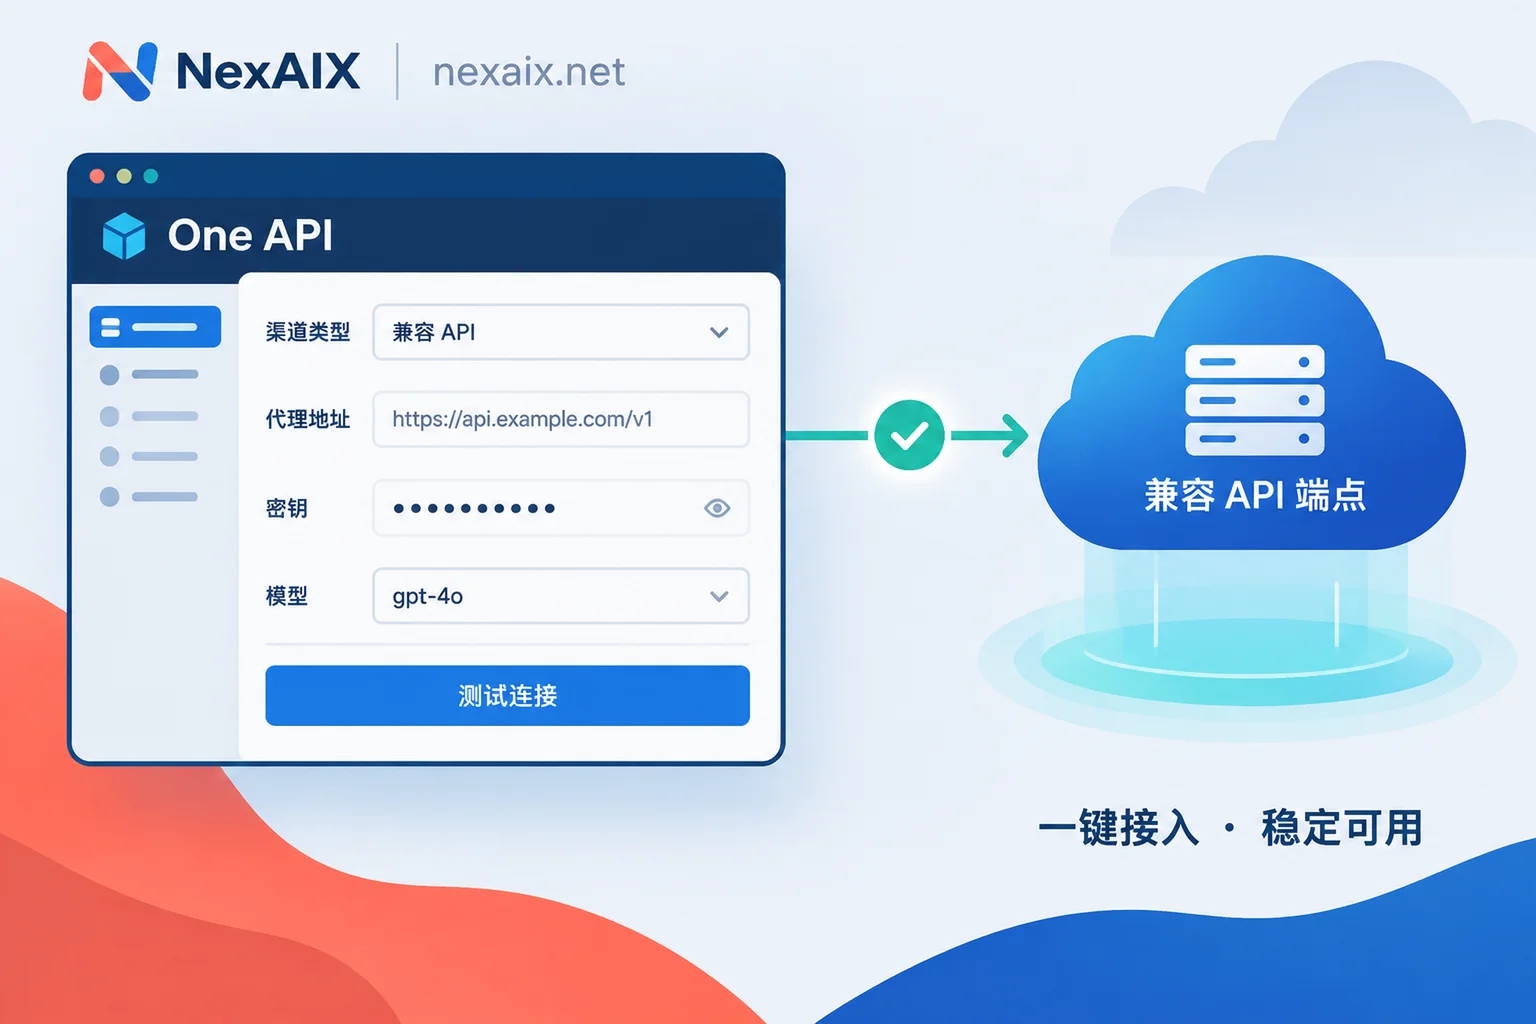
How to Add an OpenAI-Compatible Channel in One API: Proxy URL, Key, Model Name, and Test Error Troubleshooting
Add a third-party or self-hosted OpenAI-compatible channel in One API: select "OpenAI" as channel type, fill in the compatible endpoint as proxy, enter the upstream key, and manually add the exact upstream model names. Verify with the "Test" button. The article explains each form field in order and covers troubleshooting for 404, 401, and Connection refused, plus when to enable model mapping.
gpt-oss-120b API Integration Guide: Model Selection, reasoning_effort Tuning, and Downgrade Verification
A practical guide to integrating gpt-oss-120b: task selection, OpenAI-compatible endpoint setup, reasoning_effort tuning, diagnosing empty replies from tight max_tokens, and verifying quantization and routing downgrades unique to open-weight models.
Qwen3.6 API Integration Guide: Choosing Between Plus and Open-Source Versions, Thinking Mode Toggle, and Long-Context Verification
Decide whether to use Qwen3.6-Plus or the 35B-A3B / 27B open-source versions based on your task, with OpenAI-compatible endpoint code, thinking mode toggle and reasoning_content parsing, tool calling and thinking preservation notes, plus hands-on methods for verifying context and detecting silent downgrades.
Grok 4.5 API Integration Guide: Selection Criteria, 500K Context Calls, and Anti-Downgrade Verification
Decide if Grok 4.5 fits your task, then get a minimal working request via the OpenAI-compatible endpoint, reasoning_effort tiers and tool calling config, plus handling for long context, timeout truncation, and rate-limit retries, and finally verify you're getting the genuine model with fingerprints, long-context retrieval, and reasoning_tokens.