NexAIX-官方博客
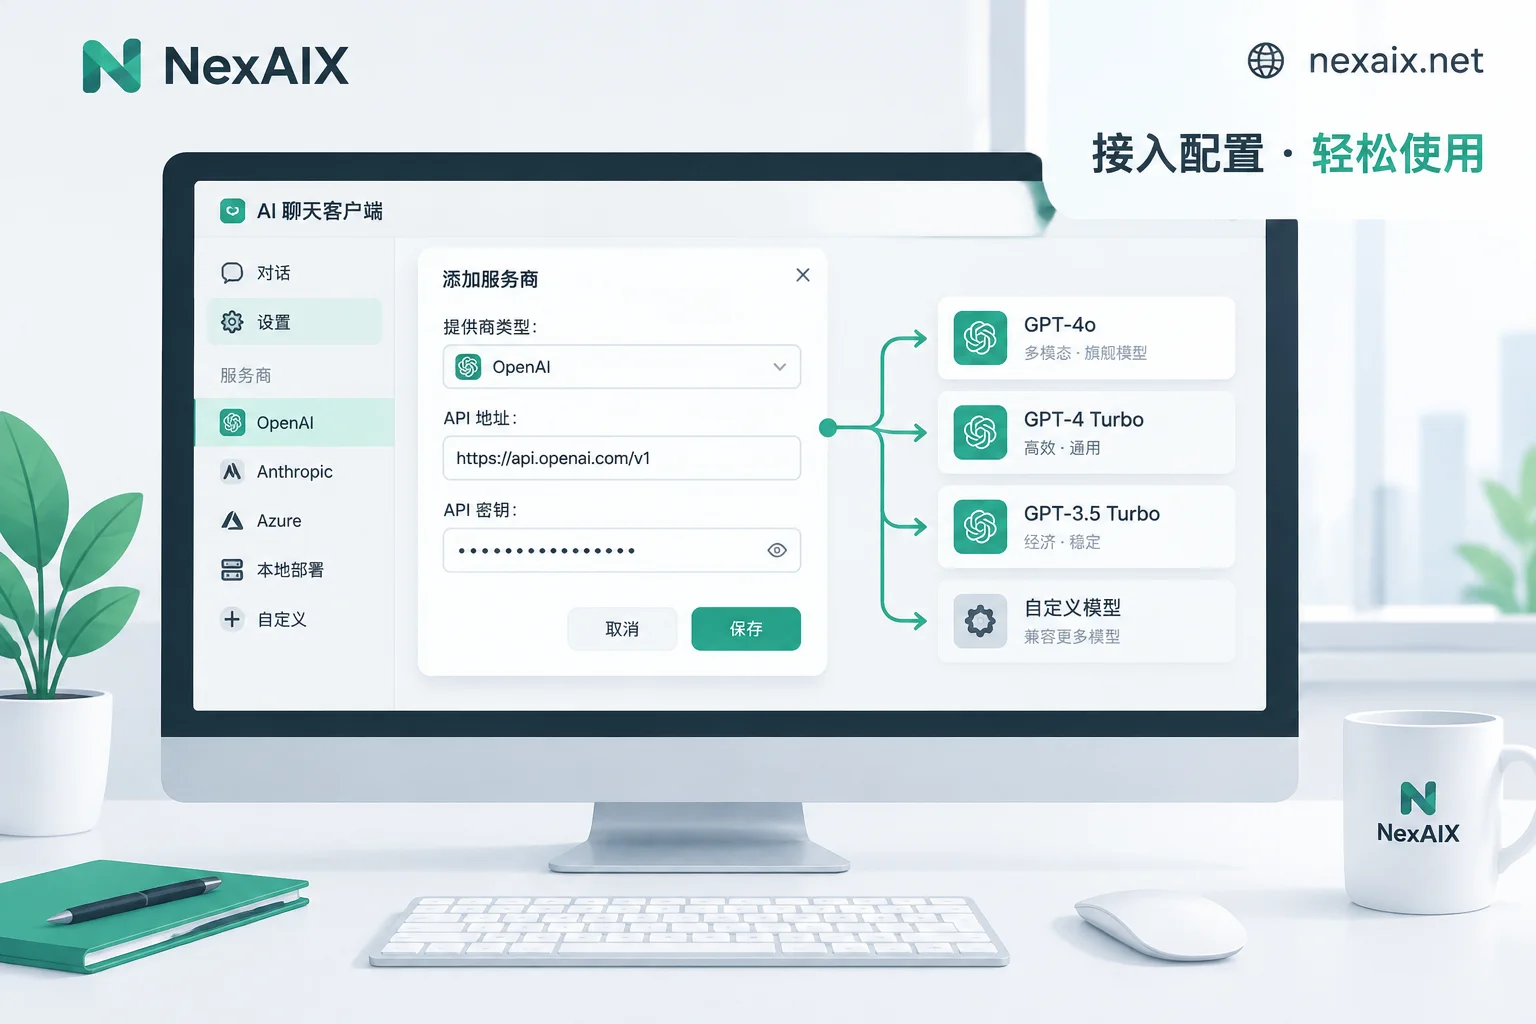
How to Add a Custom LLM in Cherry Studio: Provider, API URL, Model ID, and Troubleshooting
A complete guide to connecting any OpenAI-compatible API as a custom provider in Cherry Studio, covering whether the API URL should include /v1, how to manually add models when the list fails to load, which capability tags to select, and how to troubleshoot message failures, 401, and 404 errors after setup.
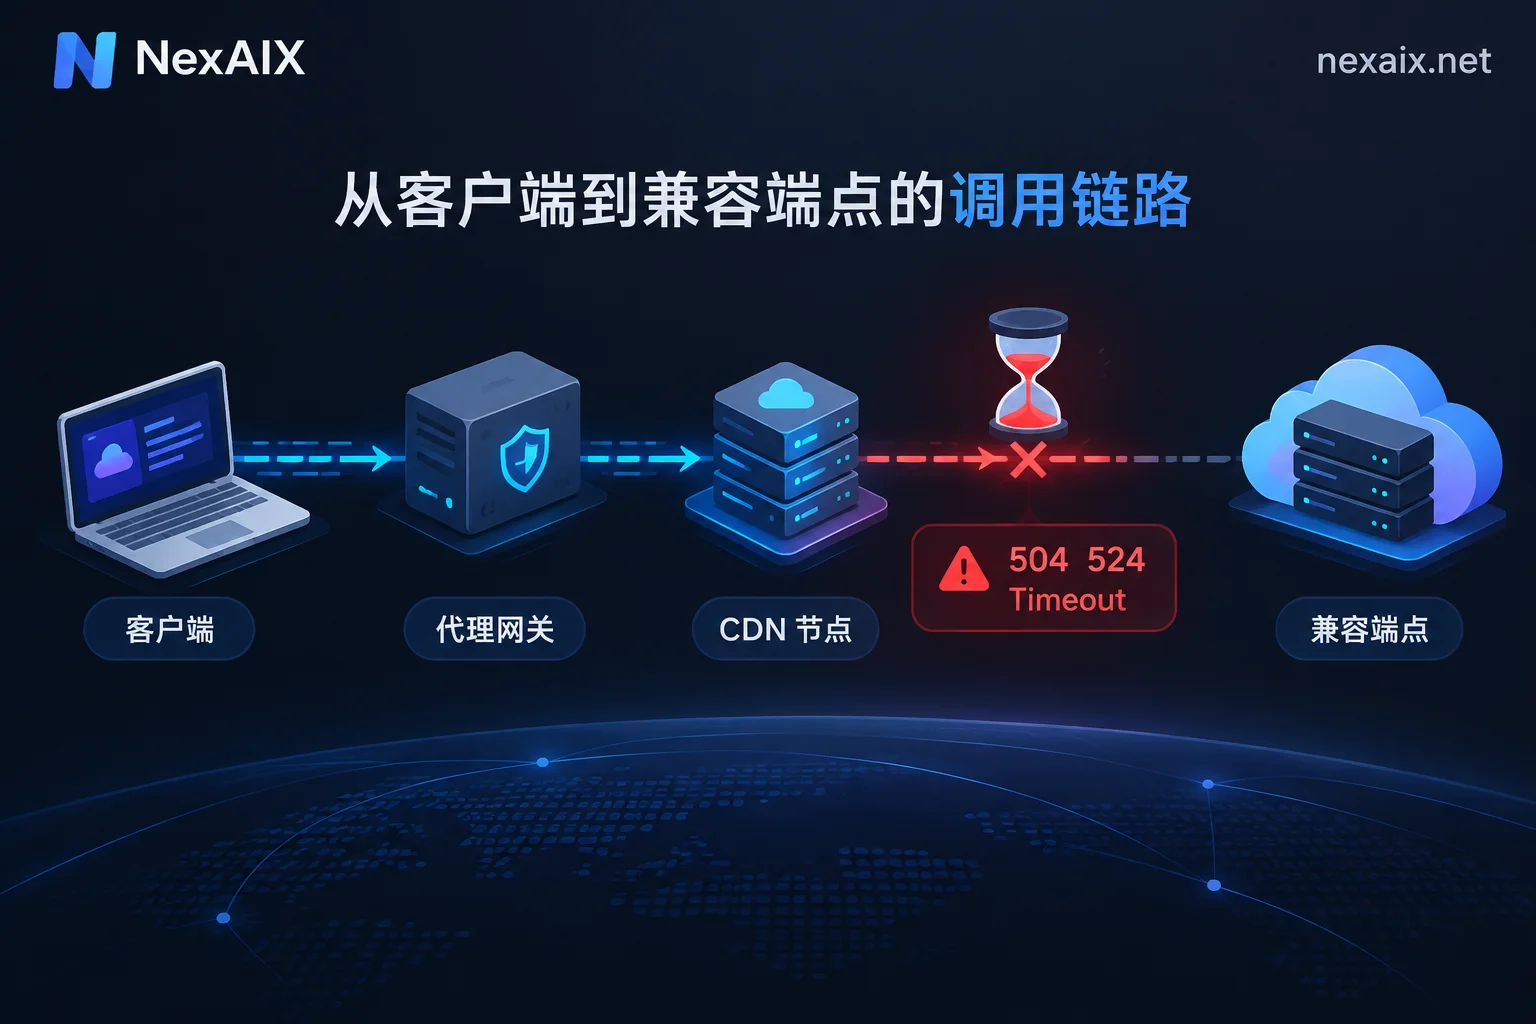
How to Fix AI API Timeouts: Tracing 504, 524, and APITimeoutError Step by Step
Most LLM request timeouts happen because long context and long outputs exceed the default wait times of the client, Nginx, or Cloudflare; this article walks through pinpointing the break point, enabling streaming, setting per-phase timeouts, adjusting proxies, and controlling retries and output length, with Python SDK and Nginx configuration examples and the conditions under which each setting applies.
Qwen3.6 API Integration Guide: Choosing Between Plus and Open-Source Versions, Thinking Mode Toggle, and Long-Context Verification
Decide whether to use Qwen3.6-Plus or the 35B-A3B / 27B open-source versions based on your task, with OpenAI-compatible endpoint code, thinking mode toggle and reasoning_content parsing, tool calling and thinking preservation notes, plus hands-on methods for verifying context and detecting silent downgrades.
Grok 4.5 API Integration Guide: Selection Criteria, 500K Context Calls, and Anti-Downgrade Verification
Decide if Grok 4.5 fits your task, then get a minimal working request via the OpenAI-compatible endpoint, reasoning_effort tiers and tool calling config, plus handling for long context, timeout truncation, and rate-limit retries, and finally verify you're getting the genuine model with fingerprints, long-context retrieval, and reasoning_tokens.
DeepSeek V4 Flash API Integration Guide: Model Name Changes, Thinking Mode, and Truncation Troubleshooting
DeepSeek V4 Flash has been upgraded to V4.1-Flash with the recommended model name deepseek-flash, so this guide covers the model field, 1M context, 384K output, thinking mode conflicts with FIM, and how to verify the model isn't downgraded after migrating to an OpenAI-compatible endpoint.