 NexAIX-官方博客
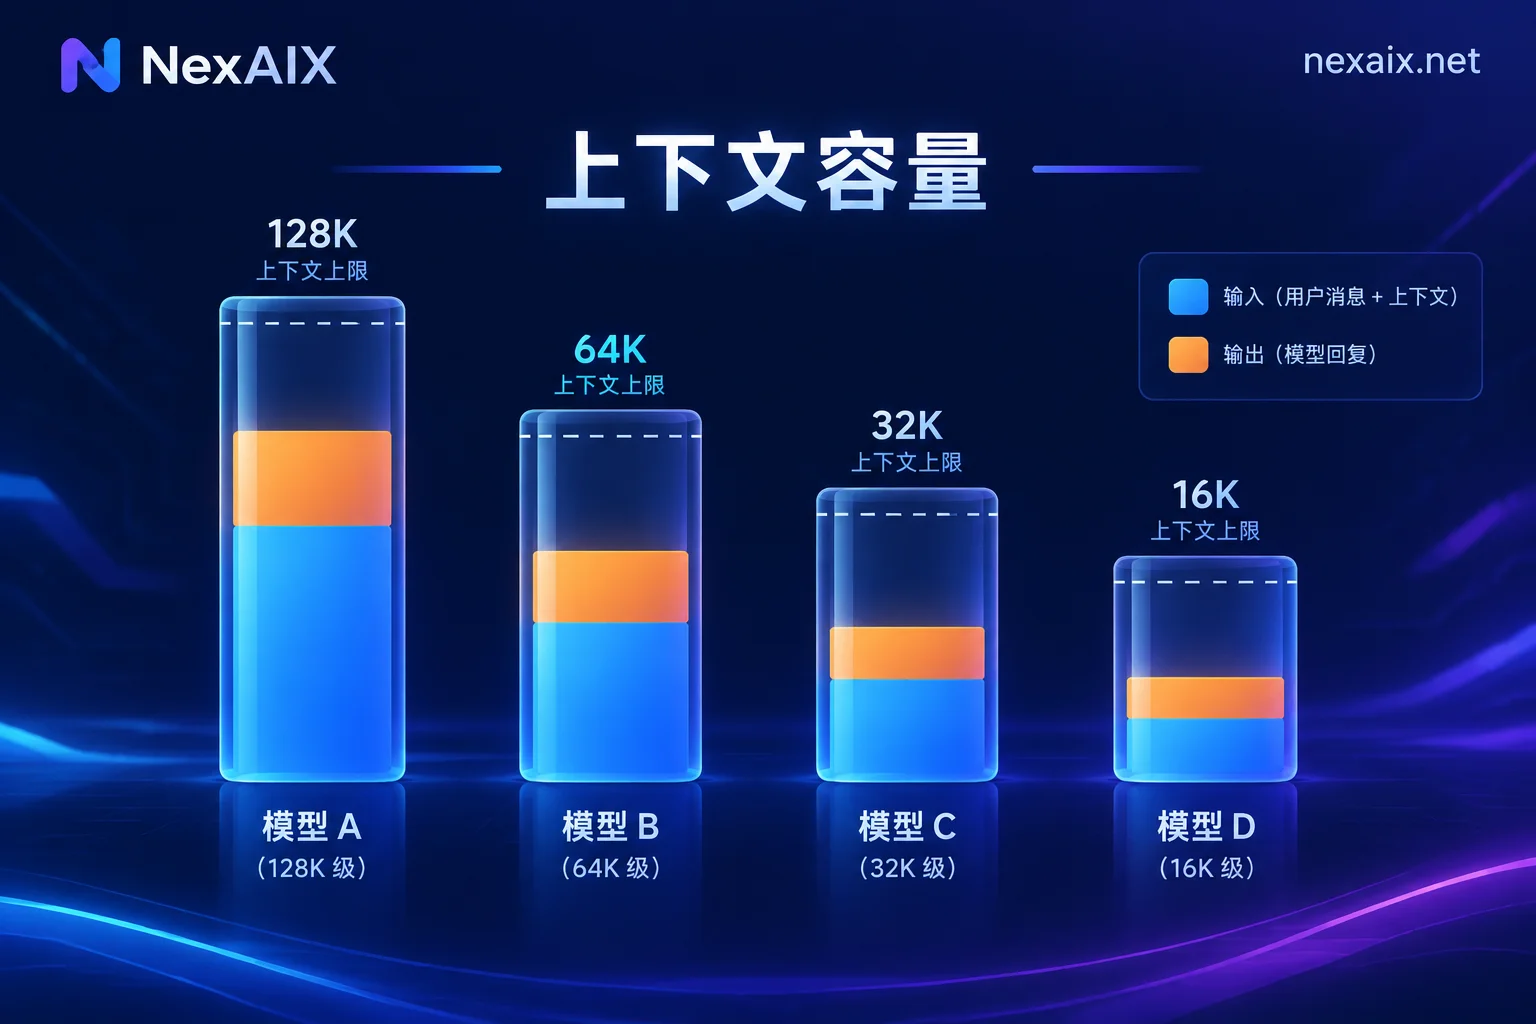
Model Context Window Comparison: How to Calculate Window and Output Limits, and Avoid Truncation, Latency, and Rate Limiting
Compare the context windows and single-output limits of representative versions like GPT-4o, Claude 3.5 Sonnet, DeepSeek-V3, and Gemini 1.5. This article explains how to calculate token budgets using "input + reserved output ≤ window" and choose the right window tier for your task. When output is truncated, use finish_reason and usage to pinpoint the cause. It also covers how to handle latency, attention decay, and TPM rate limiting caused by long contexts.
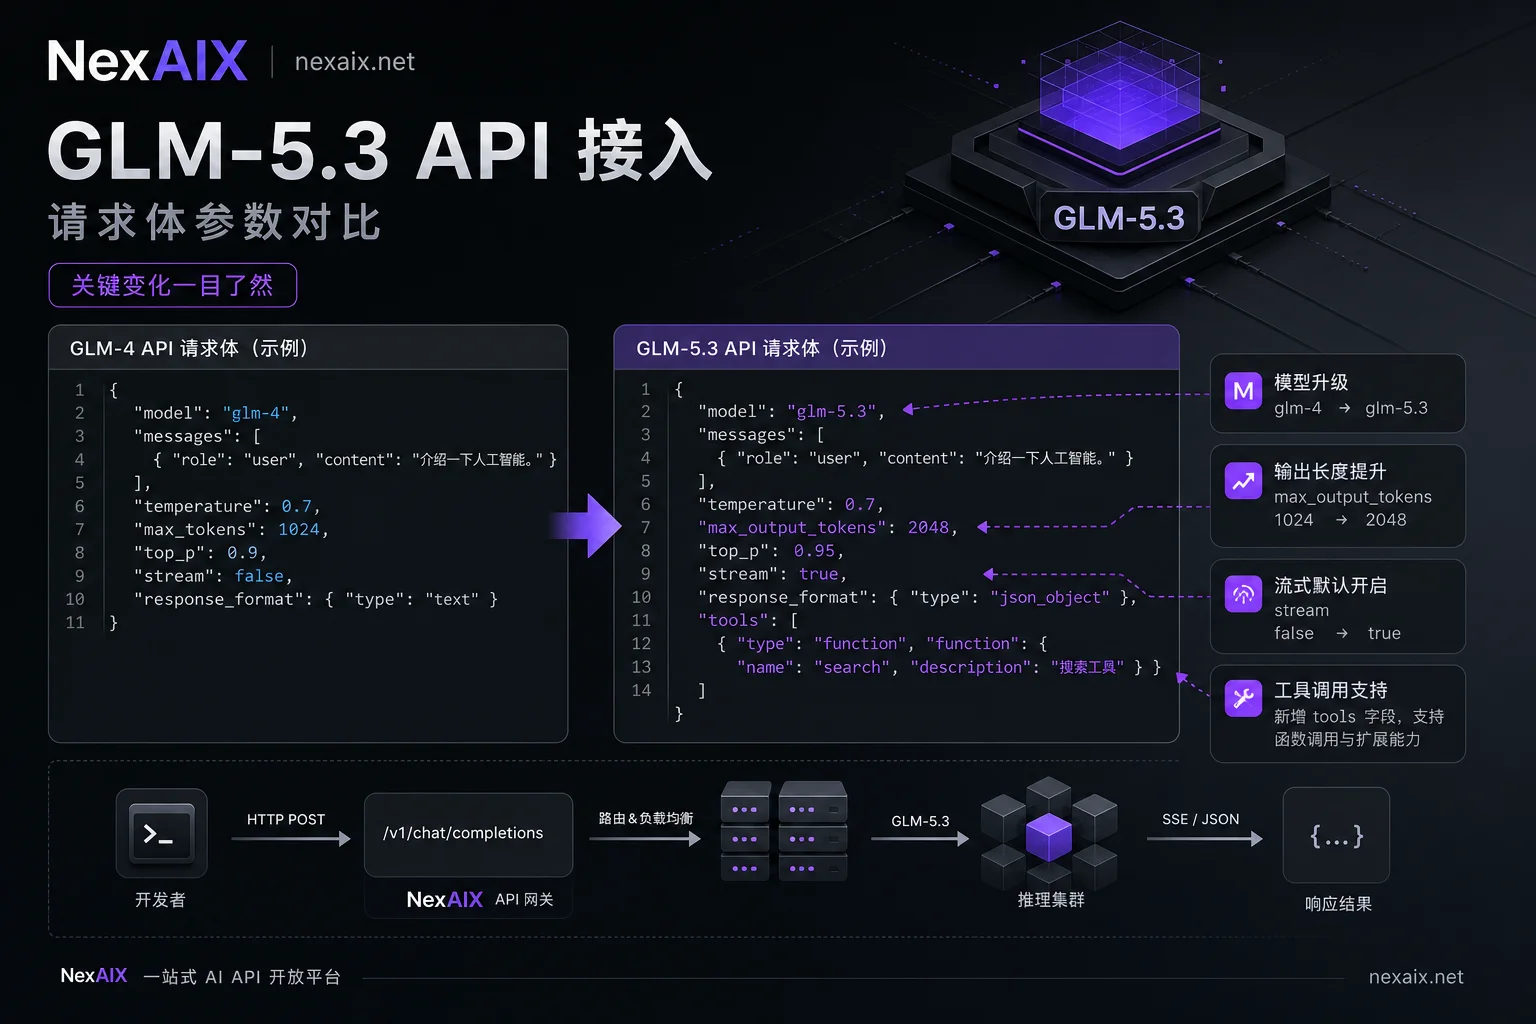
GLM-5.3 API Integration: Critical Parameters to Change and Migration Checklist
Learn the key parameter changes for GLM-5.3 API integration, including the breaking change of thinking.type='disabled', migration across three endpoints, and a verification checklist.


