 NexAIX-官方博客
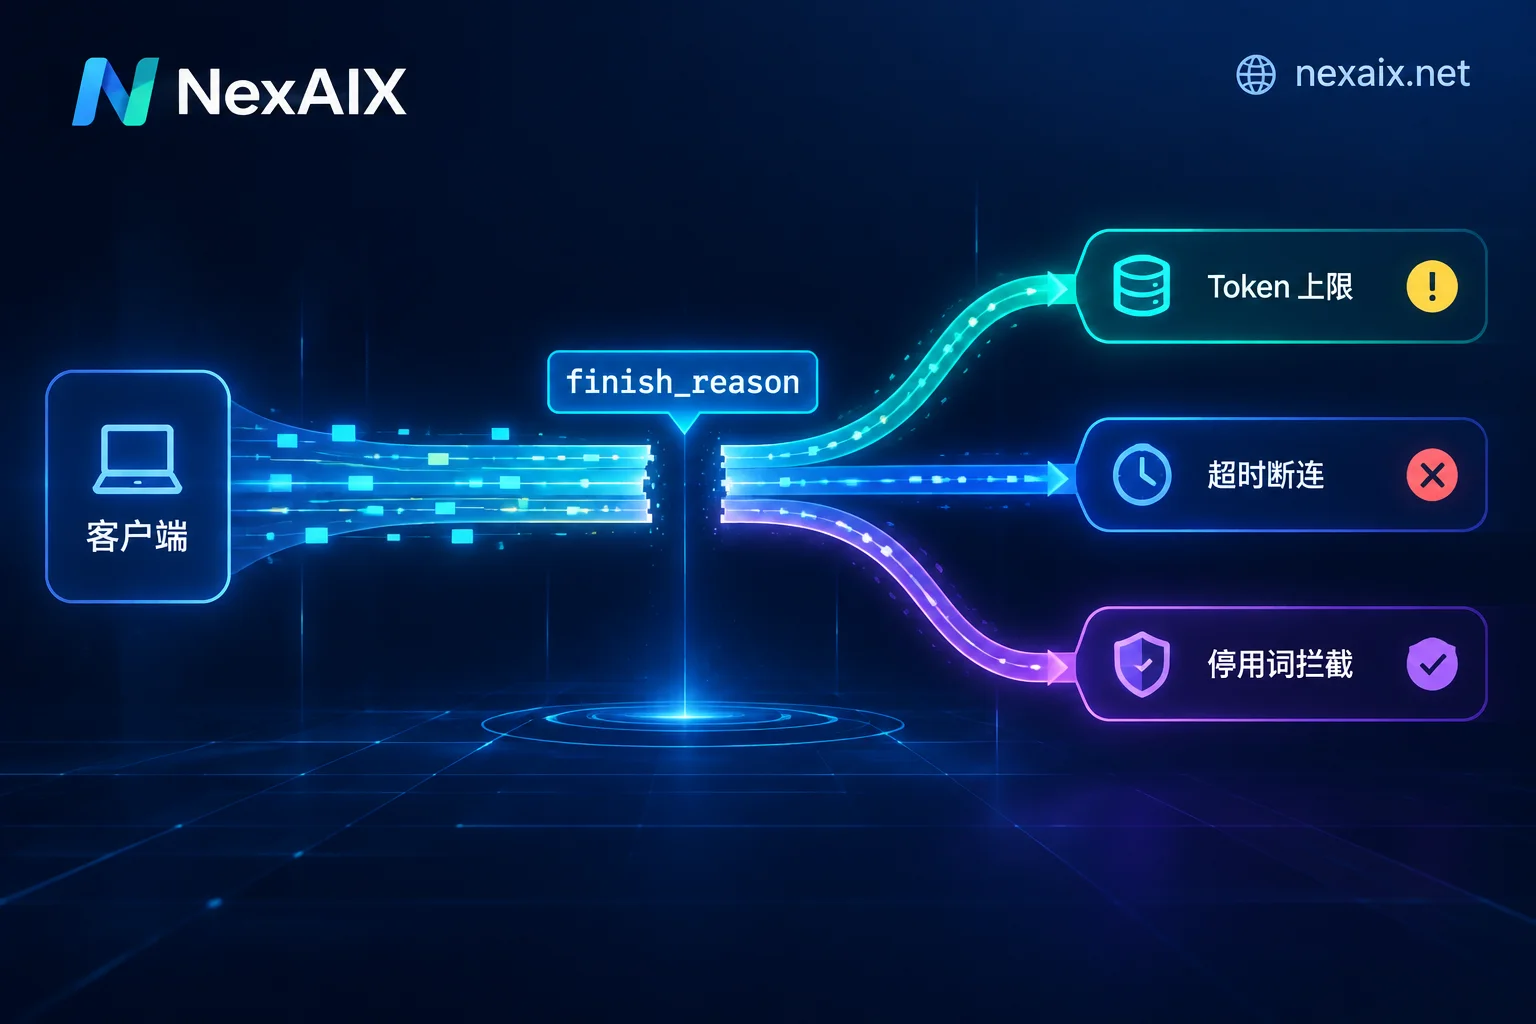
What to Do When LLM API Output Is Truncated: Check finish_reason First, Then Fix by Cause
Truncated LLM API output—half-finished sentences, unclosed JSON, interrupted streams—usually has only four causes: hitting the token limit, reasoning models consuming output budget with chain-of-thought, tasks exceeding the model's single-call max output, and client or proxy timeouts.
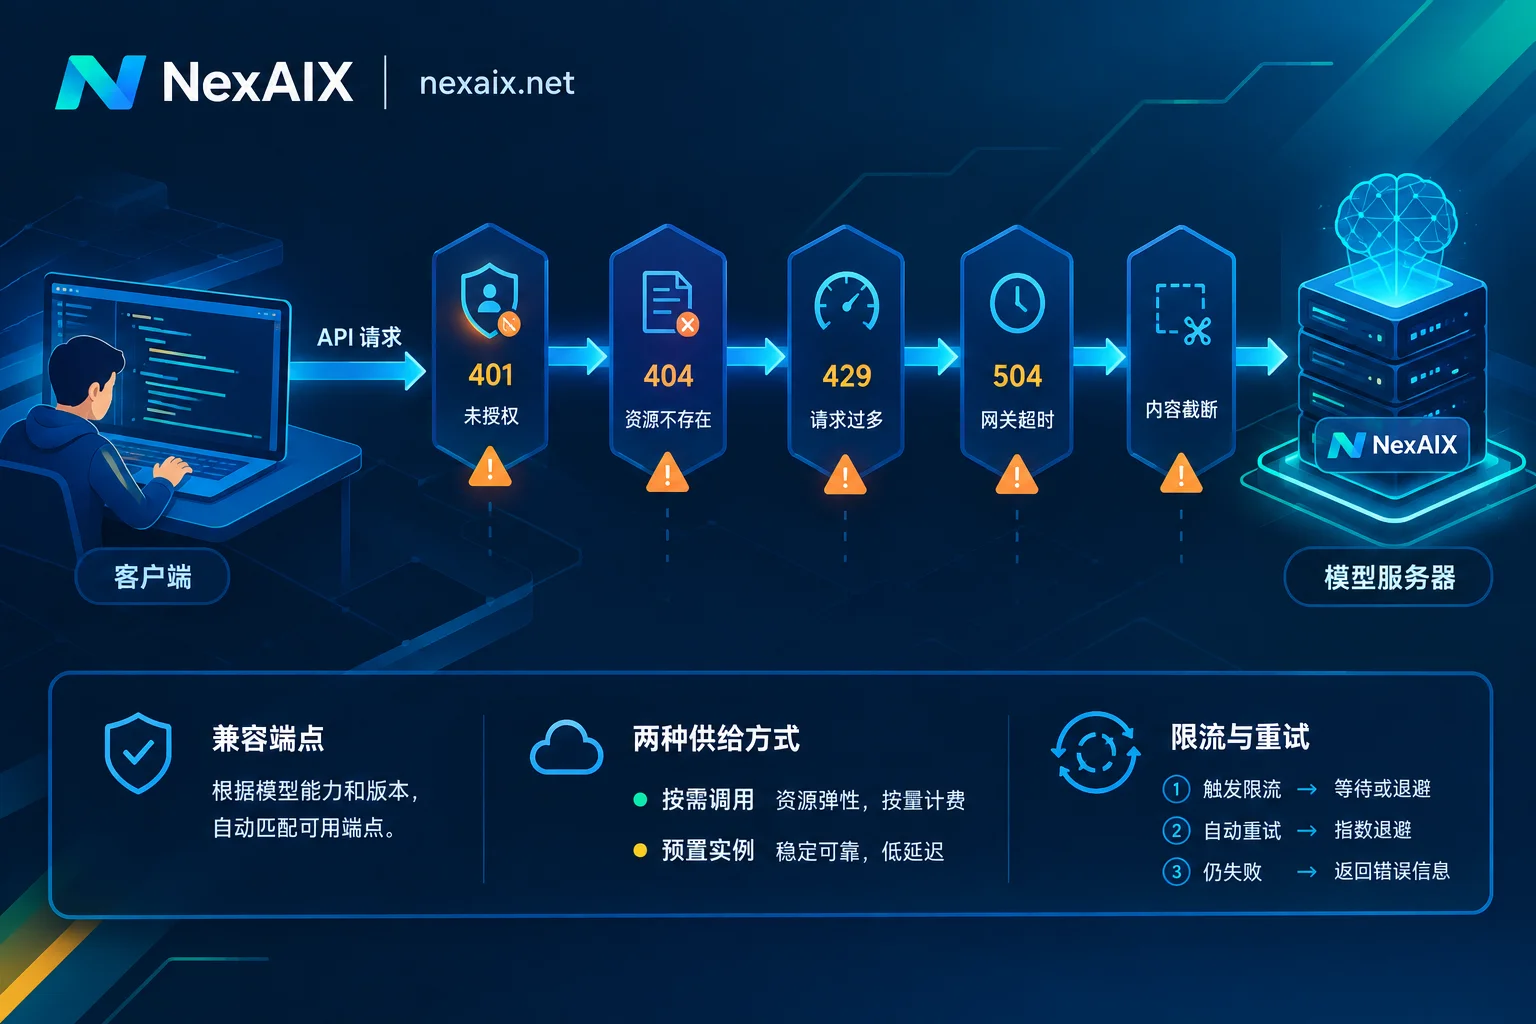
AI API Troubleshooting: From 401, 404, 429 to Timeouts, Truncation, and Suspected Model Downgrades, Locate in Order
When calling a large model API, first look at the status code and the error type in the response body, then use a minimal request to determine whether the problem is on the client or server side. This article explains how to diagnose and handle each type of issue in order: authentication, path and model ID, rate limiting and quotas, 5xx and timeouts, context truncation, and downgrade verification.


