 NexAIX-官方博客
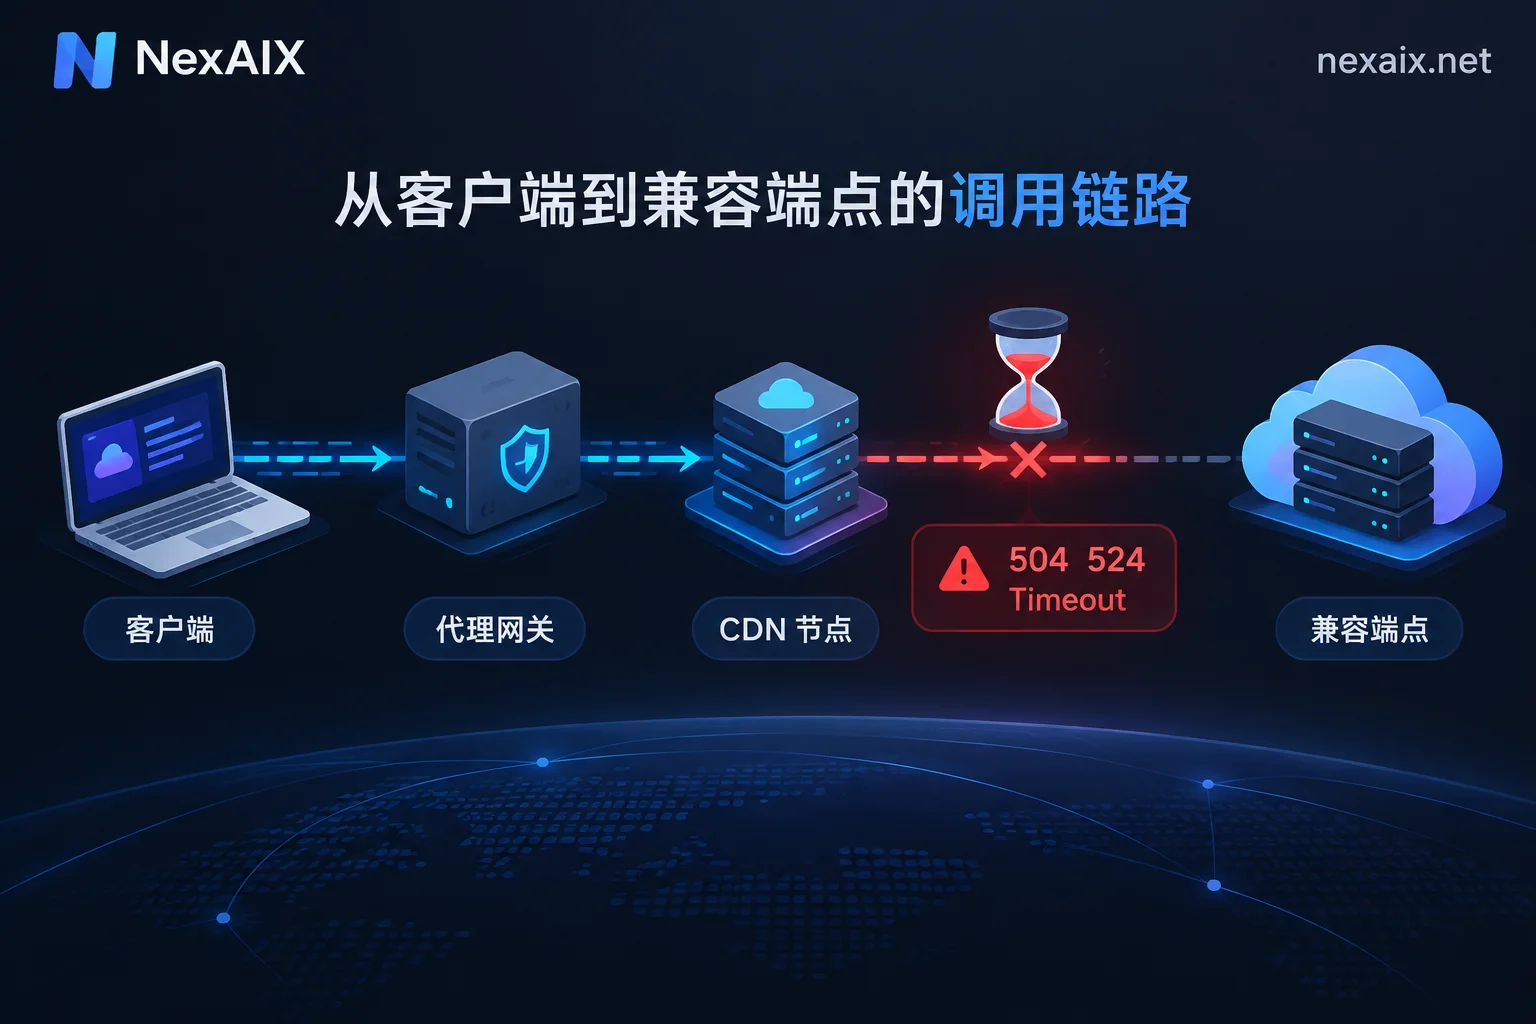
How to Fix AI API Timeouts: Tracing 504, 524, and APITimeoutError Step by Step
Most LLM request timeouts happen because long context and long outputs exceed the default wait times of the client, Nginx, or Cloudflare; this article walks through pinpointing the break point, enabling streaming, setting per-phase timeouts, adjusting proxies, and controlling retries and output length, with Python SDK and Nginx configuration examples and the conditions under which each setting applies.
How to Integrate a Streaming Output API: SSE Parsing, Token Usage, and Proxy Buffering Troubleshooting
Starting from a working curl command, this guide explains the SSE message structure of streaming output APIs, the empty choices and cross-packet issues easily missed during parsing, how to get token usage with stream_options, the troubleshooting order for reverse proxy buffering that causes one-shot output, and how to abort upstream requests when the client disconnects.


