 NexAIX-官方博客
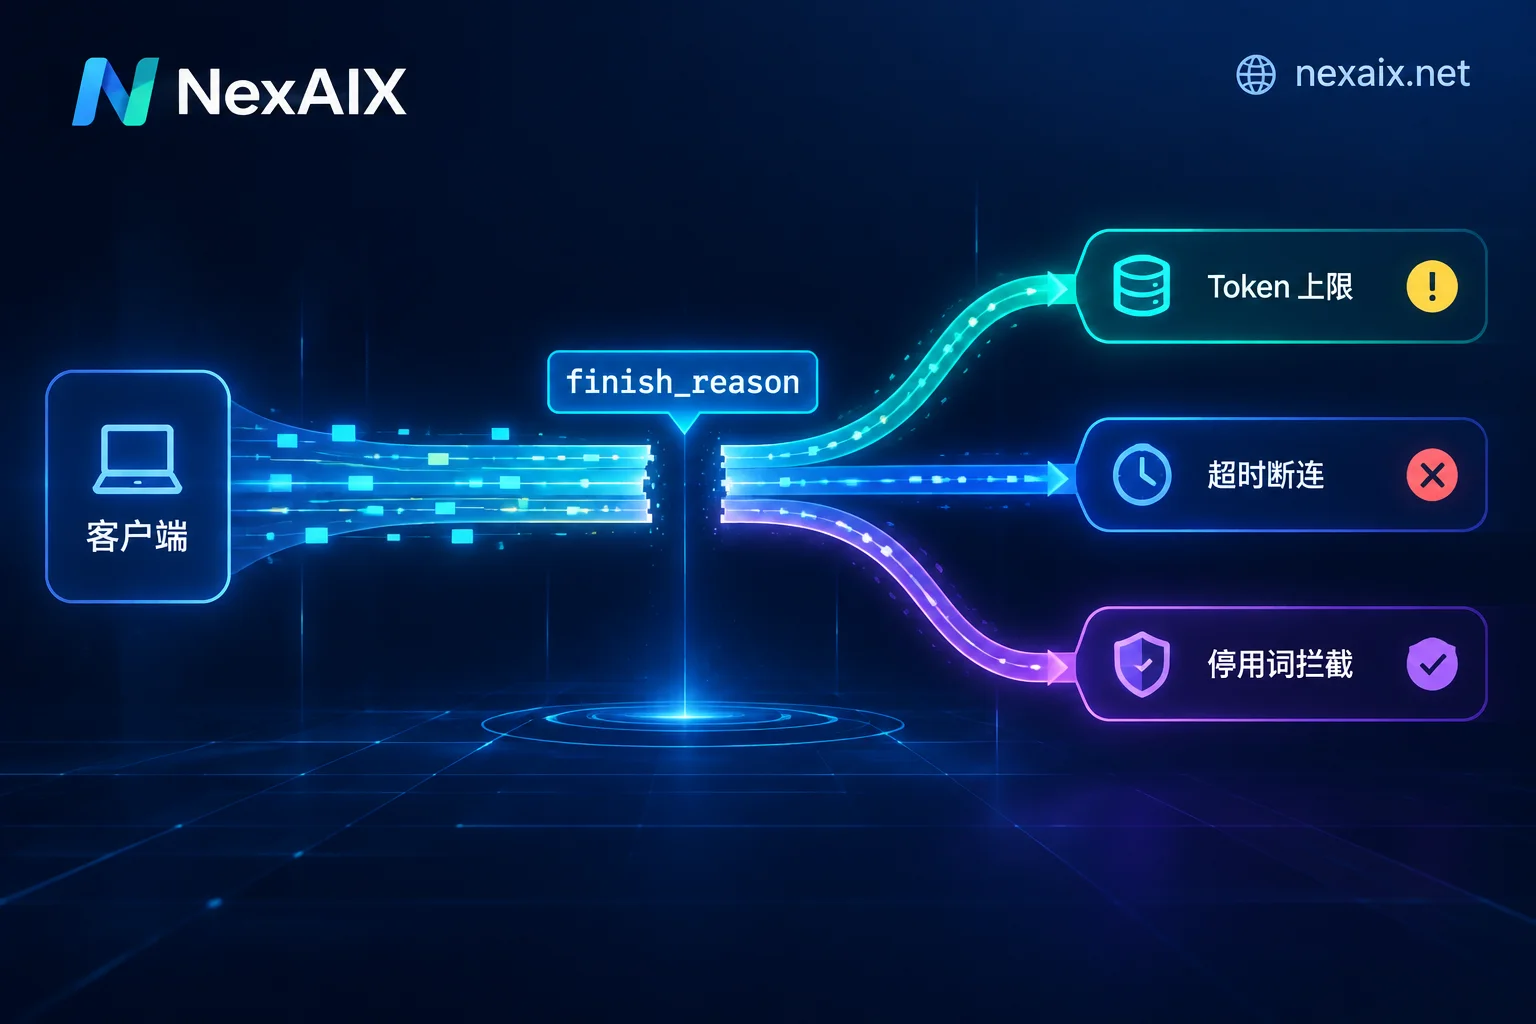
What to Do When LLM API Output Is Truncated: Check finish_reason First, Then Fix by Cause
Truncated LLM API output—half-finished sentences, unclosed JSON, interrupted streams—usually has only four causes: hitting the token limit, reasoning models consuming output budget with chain-of-thought, tasks exceeding the model's single-call max output, and client or proxy timeouts.
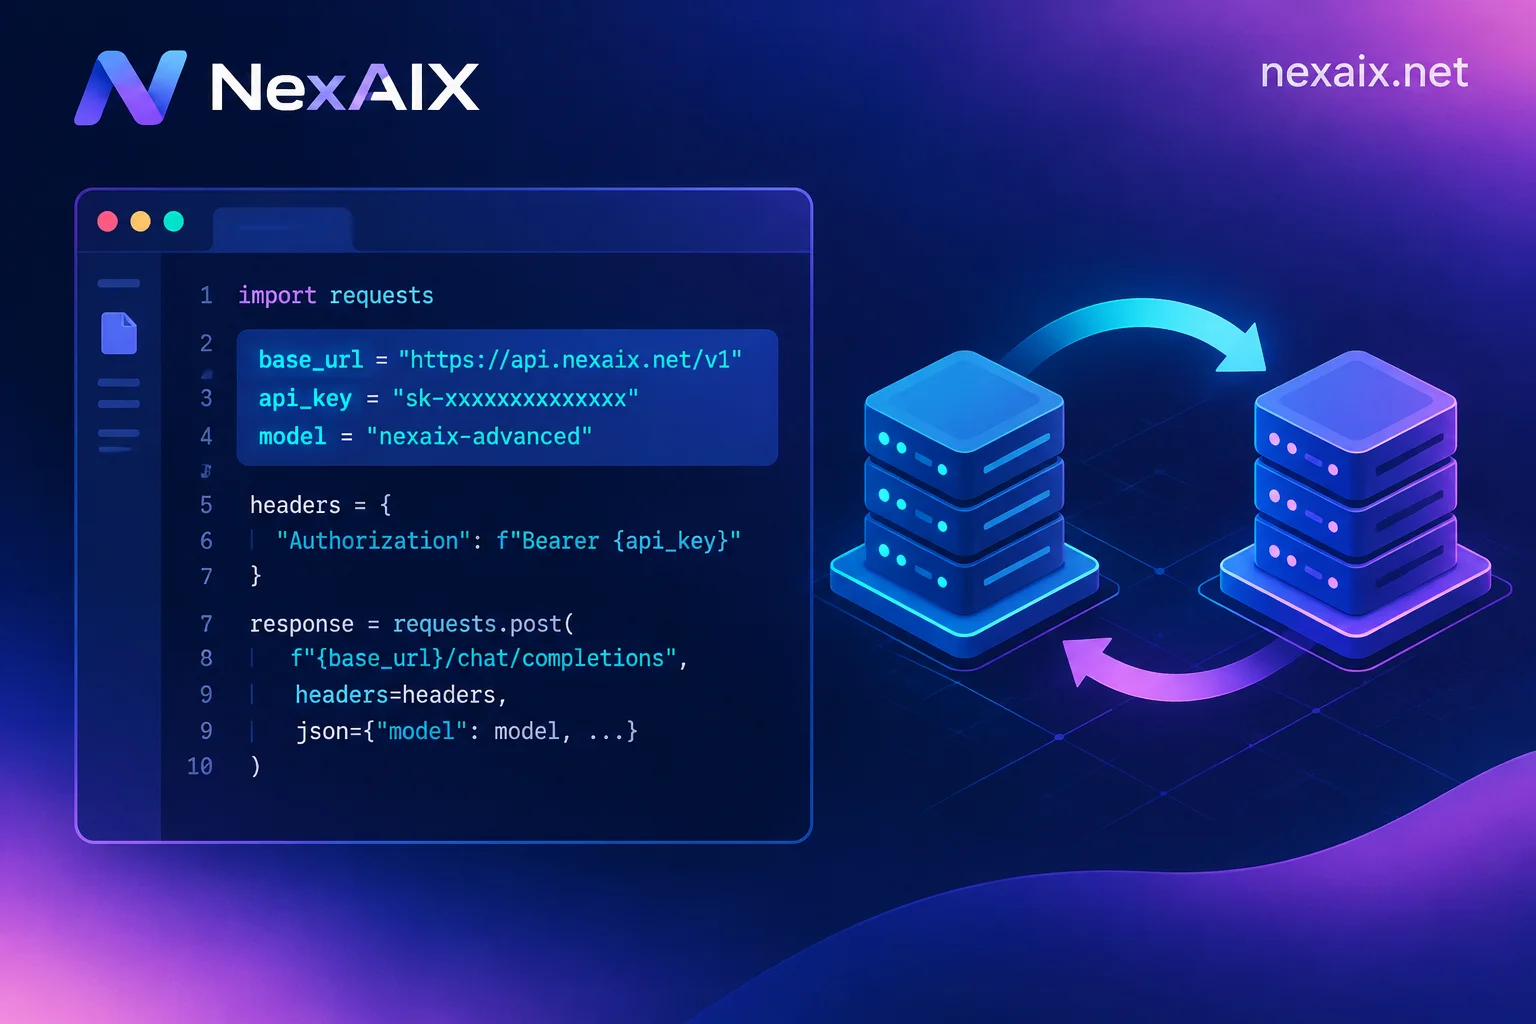
What Code to Change When Switching LLM APIs: Three Must-Change Configs and Four Compatibility Checks
When staying on the OpenAI-compatible protocol, switching models usually requires changing only base_url, api_key, and model—but if your code uses length parameters, sampling parameters, streaming usage, tool calling, or structured outputs, verify each against the target model.
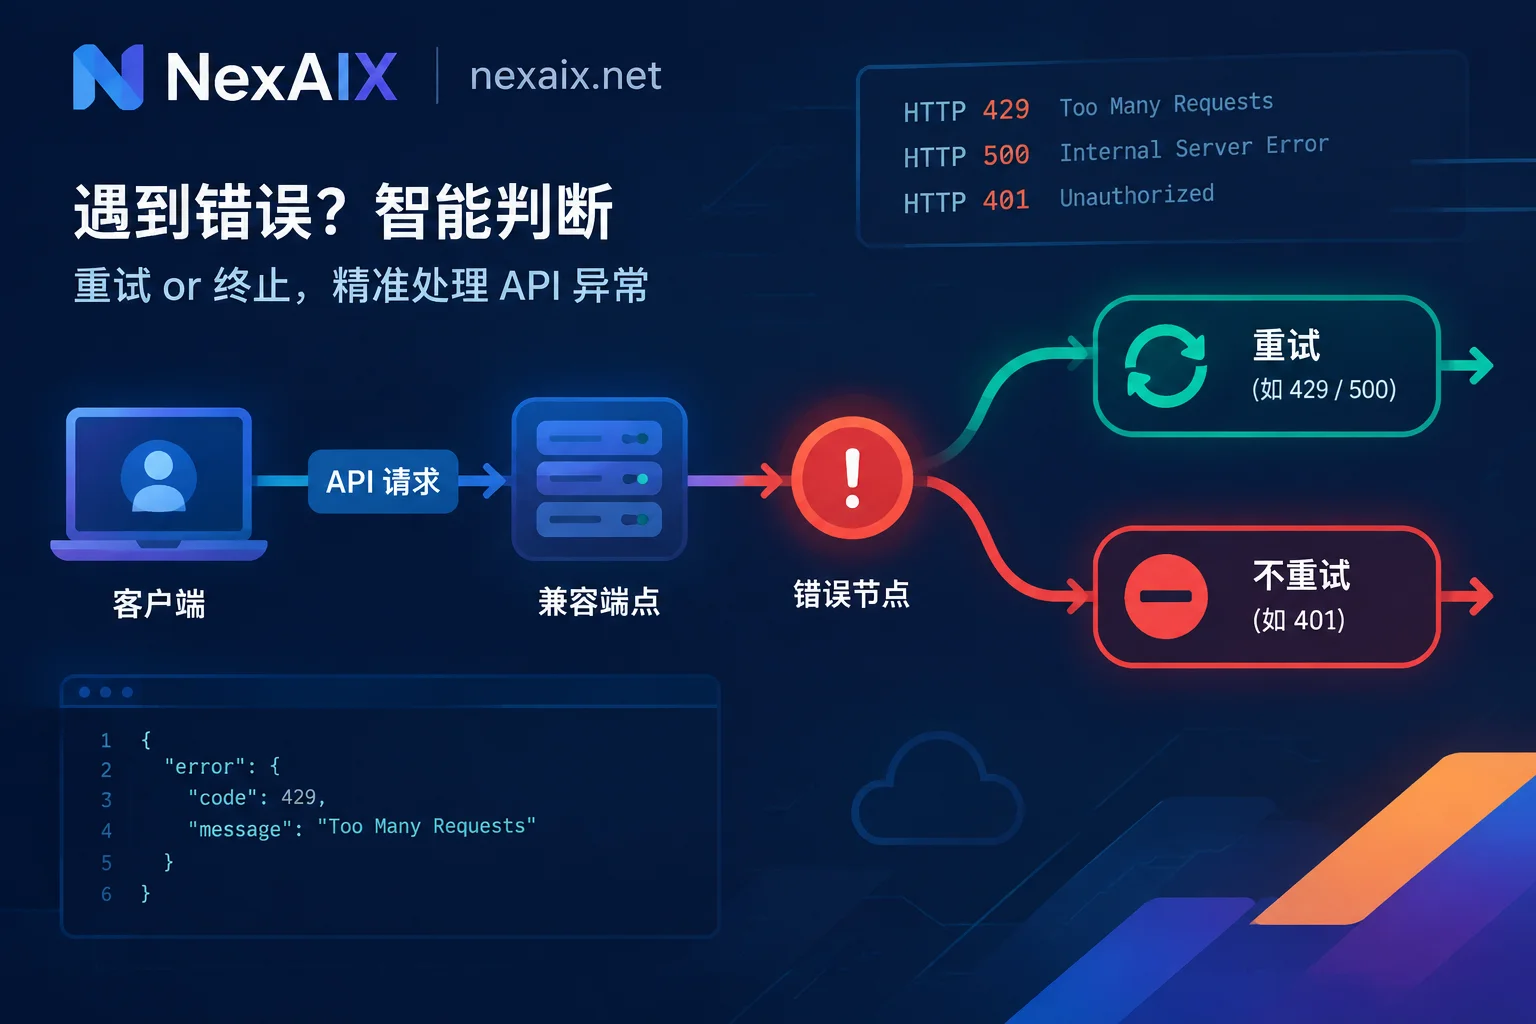
How to Design AI API Retries: What to Retry, How Long to Back Off, and What to Do When a Stream Breaks
Split LLM call errors into retryable transient failures and deterministic failures that retrying won't fix, with parameter choices for Retry-After priority and jittered exponential backoff, plus handling for three common traps: stream interruptions, nested SDK retries, and tool-call side effects.


