 NexAIX-官方博客
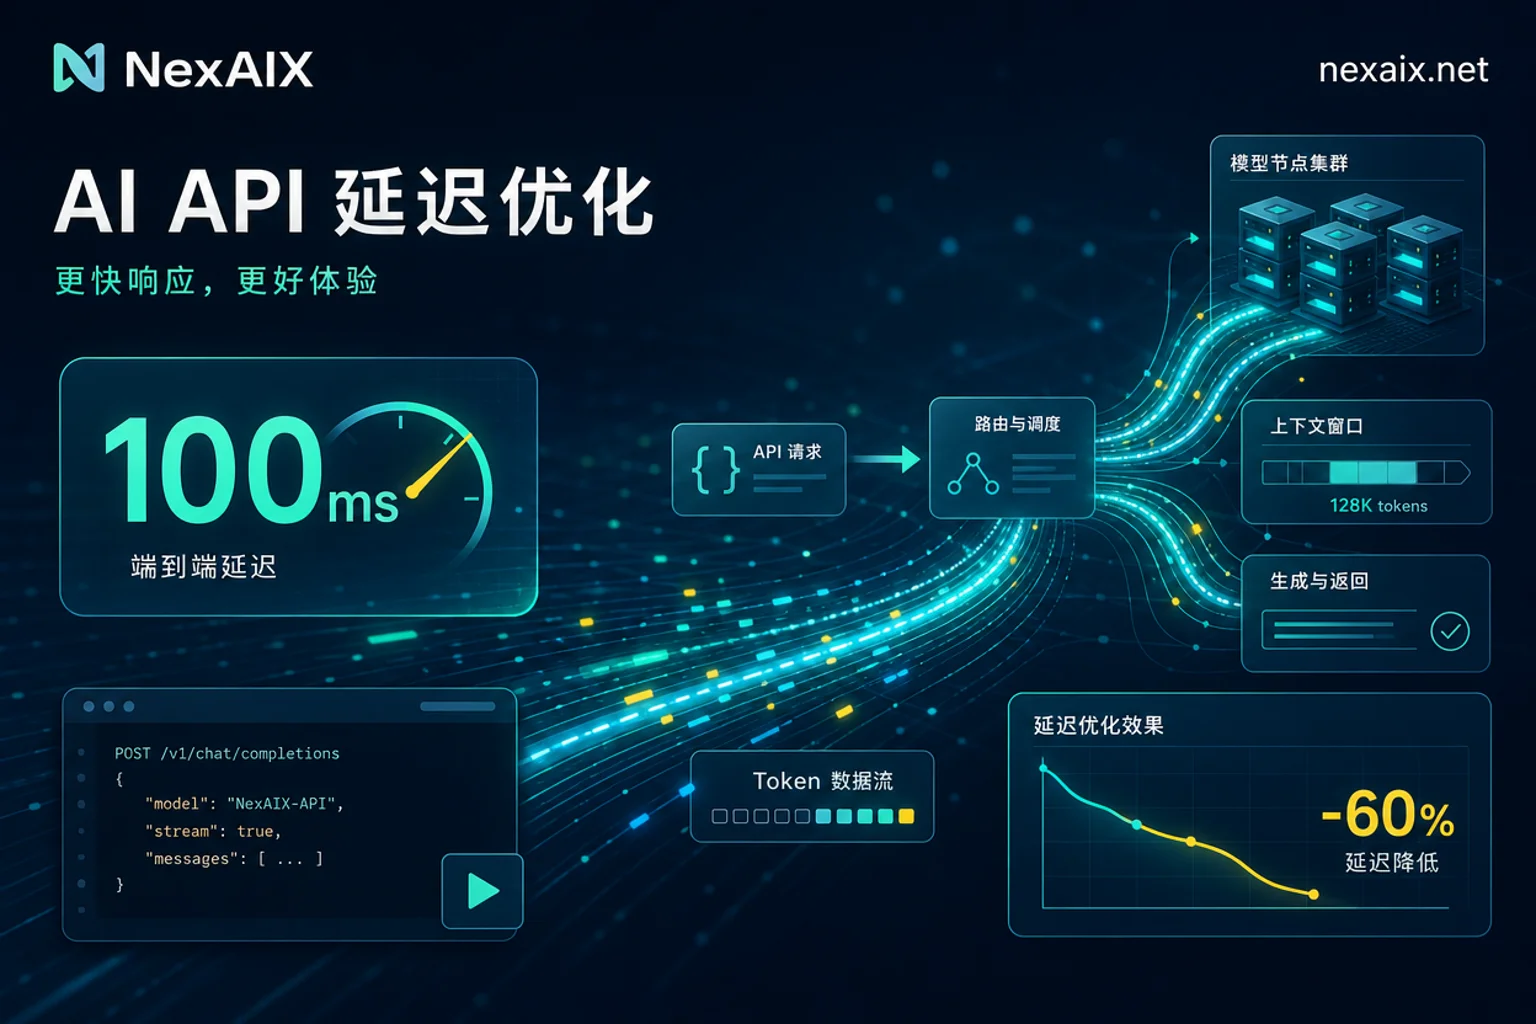
How to Keep AI API Latency Under 100ms? Break Down Controllable Factors and Baseline Lines
A practical guide to understanding and optimizing AI API latency, focusing on controllable factors, baseline metrics, and trade-offs between client-side actions and server-side inference stacks.
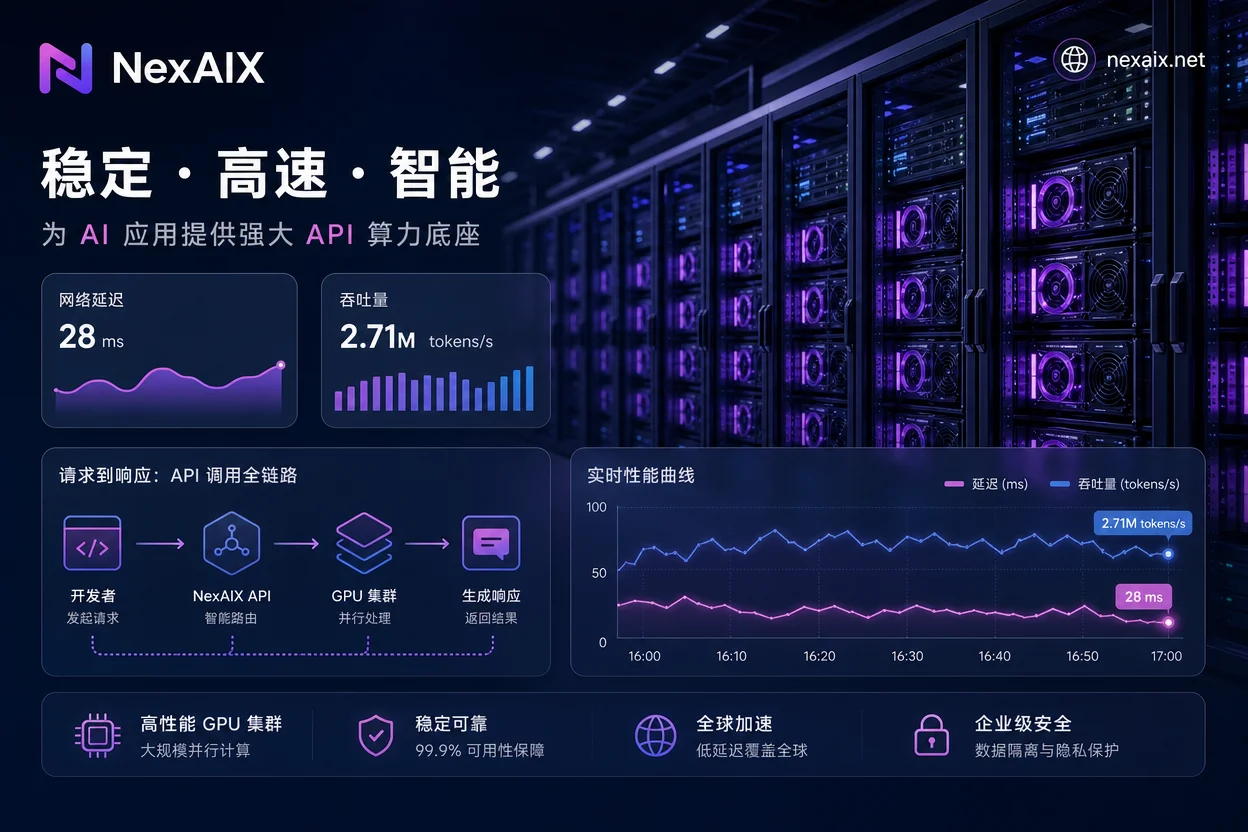
DeepInfra's TTFT/Throughput/E2E Framework: How Load Testing Reveals Performance Inflation in Self-Hosted AI APIs vs. Relay Stations
Learn to measure TTFT, throughput, and E2E latency to distinguish genuine self-hosted AI APIs from potentially inflated relay stations, with a reproducible load testing protocol and supplier acceptance checklist.


